


What test data management is, the types of test data, the main techniques, the TDM process and strategy, compliance, a worked checkout example, and how to choose a TDM tool.
Test data management decides which data each test gets, where it comes from, and how it stays safe and current. This guide covers what test data management is, the types of test data, the main techniques, the process step by step, how to build a strategy, compliance, a worked example, and how to choose a test data management tool.
What is test data management?
Test data management (TDM) is the practice of defining, creating, masking, provisioning, and maintaining the data that tests need in non-production environments. Its goal is the right data for each test, in the right format, at the right time, without exposing real customer data.
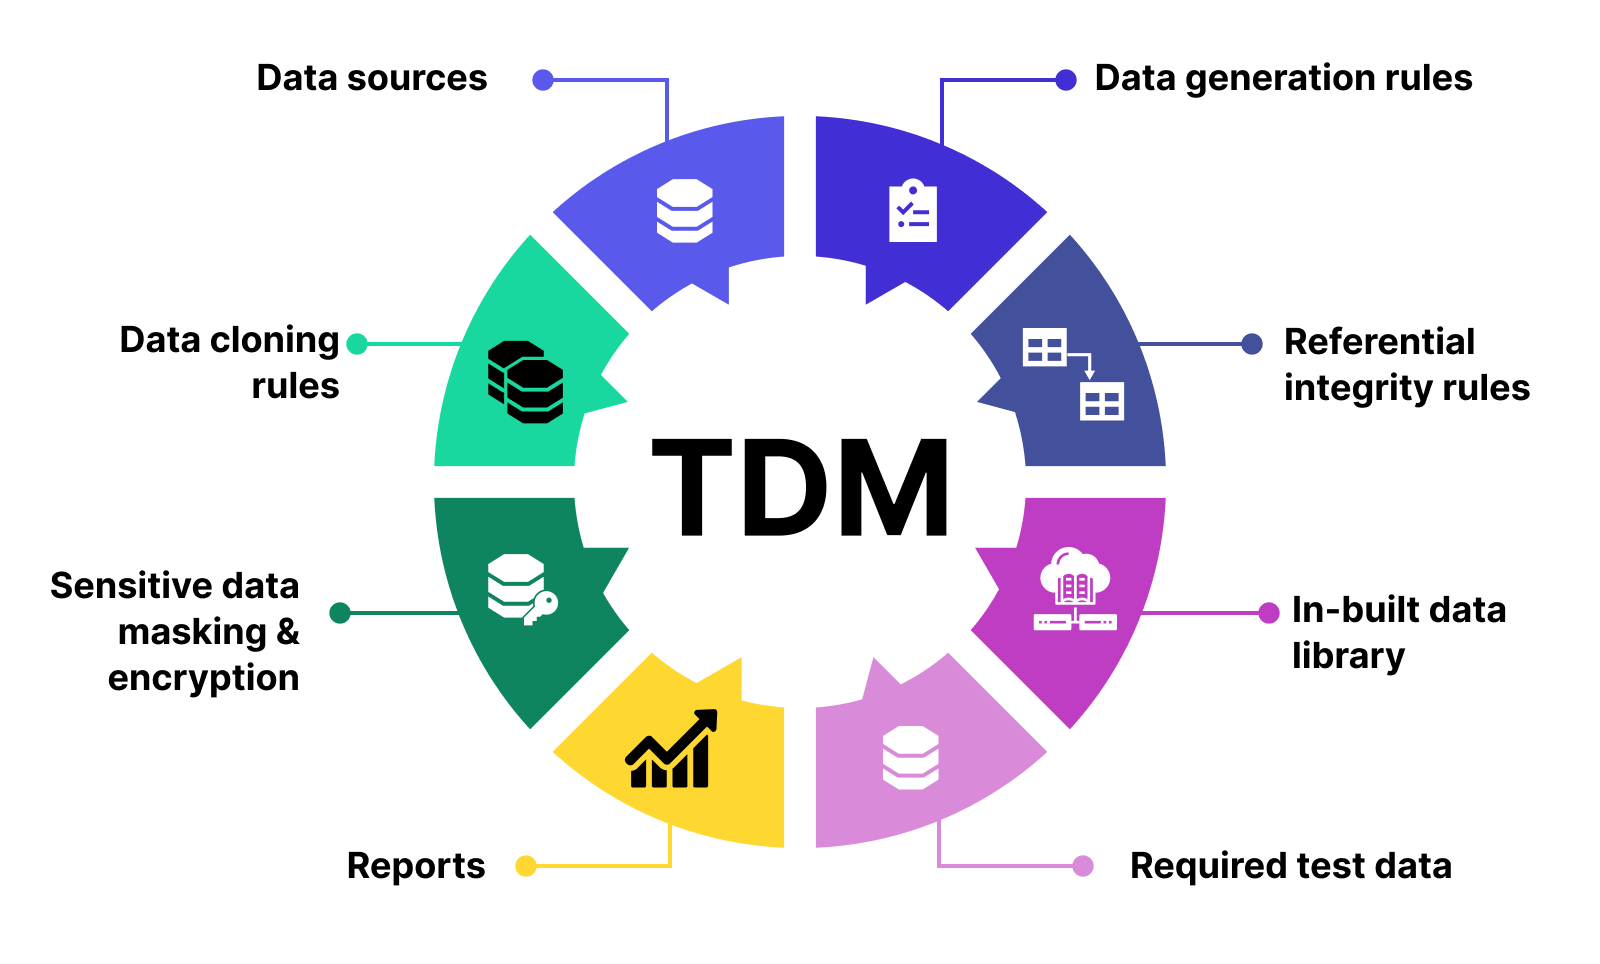
In practice, TDM covers finding sensitive data, masking it, cutting databases down to useful subsets, generating synthetic data, cloning or virtualizing databases, getting data to test environments, and refreshing it after tests change it. It is one part of test management: the test plan says which test data a release needs, and TDM is how that data gets made and delivered.
What is test data?
Test data is the set of inputs, records, and system states a test needs to run and check a result. That can be a username and password, a customer with 3 past orders, an expired card, or a product that is out of stock.
For example, test data for a login page usually has 2 columns, Username and Password. A test script opens the login page, fills in each pair, and checks the response:
Username | Password |
|---|---|
user_123 | Pass123! |
testuser@email | Secret@321 |
admin_user | AdminPass# |
jane_doe | JaneDoePass |
Good test data meets 4 criteria:
- Relevant: it matches the scenario under test. A wrong-password test that uses a valid password gives a false result.
- Available: the people and pipelines that need it can get it when they need it, with access limited to the right roles.
- Current: it reflects the application as it is now. A schema change or a new required field can make old data useless.
- Compliant: it doesn't expose personal, health, or payment data that privacy rules protect.
Types of test data
Test data can be grouped by where it comes from. Most teams use several of these at once.
Type | What it is | Example | Watch out for |
|---|---|---|---|
Production copy | A full copy of the live database | Last night's backup restored to staging | Personal data, size, and cost; rarely the right choice without masking |
Masked data | Production data with sensitive fields replaced or hidden | Customer names and emails swapped for realistic fake ones | Masking has to stay consistent across tables and systems |
Subset | A small slice of production that keeps related records together | 1,000 customers with all their orders and addresses | Missing foreign keys break joins and tests |
Synthetic data | Artificial data generated from rules or models | 500 customers with valid but fictional addresses | Only as realistic as the rules behind it |
Hand-crafted data | Records a tester writes by hand for a specific case | A customer whose name has an apostrophe and accented letters | Hard to scale and easy to forget to update |
Generated on the fly | Data a test creates at runtime and cleans up after | A test signs up a new user with a unique email for each run | Needs reliable setup and teardown |
Within each type, tests also need different input categories:
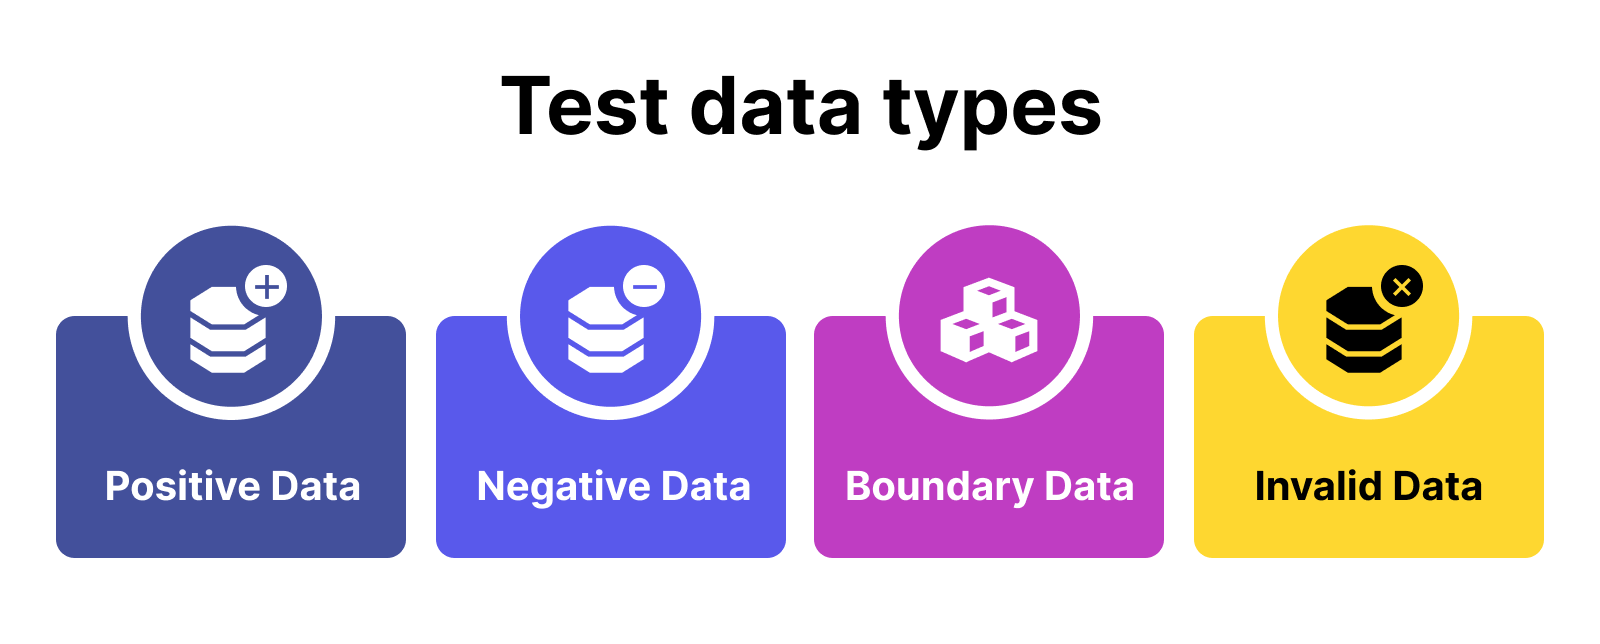
- Positive data: valid inputs within the expected range, such as a correct username and password.
- Negative data: invalid or unexpected inputs, such as a wrong password, a malformed email, or an SQL injection string.
- Boundary data: values at the edges of allowed ranges, such as a password at the minimum and maximum length.
- Null or empty data: missing values, such as an empty username field.
- Volume data: large data sets for performance and load tests.
Why test data management matters
Diversity
Test coverage depends on having data for every scenario you want to test. A simple registration page already needs data for many cases:
- Valid details
- Empty username
- Empty password
- Username already taken
- SQL injection attempt
- Special characters
- Username that is too long
- Password that is too long
TDM makes sure that data exists, is labeled, and can be reused, instead of being typed in again for each test cycle.
Data privacy
Without TDM, testers can end up using personally identifiable information (PII) in test environments, which usually have weaker access controls than production. Anonymization, masking, and synthetic data replace real values with realistic fictional ones, so tests behave the same without exposing real people.
Data consistency
Test data has to follow the same formats and rules across systems, and the relationships between records have to hold as the system grows. If a customer ID changes in one table but not in another, tests fail for reasons that have nothing to do with the code. For checks on the database itself, see our guide to database testing.
Why not just copy production?
Copying production looks fast, but it brings privacy and regulatory exposure, large and costly environments, data that changes under your tests, and few of the edge cases you need. TDM keeps production's realism and removes most of those problems. For the common obstacles teams hit along the way, see test data management challenges.
Test data management techniques
Technique | What it does | Best for | Watch-outs |
|---|---|---|---|
Data discovery and classification | Finds and labels personal, health, and payment data in source systems | Any copy of production data | Needs re-running when schemas change |
Data masking | Replaces or hides sensitive values while keeping format | Realistic data for regression and UAT | Must be consistent across systems so joins still work |
Data subsetting | Extracts a small slice that keeps related records | Smaller, faster environments | Needs referential integrity |
Synthetic data generation | Creates artificial data from rules or models | Edge cases, new features, sharing with vendors | Realism depends on the rules |
Virtualization and cloning | Gives each environment a lightweight copy you can reset | Fast refresh and rollback, parallel environments | Needs tooling and storage planning |
Refresh and reservation | Resets data to a known state and stops tests from sharing records | Automation and parallel runs | Needs an owner and a schedule |
Data discovery and classification
Discovery scans source databases and files to find where personal, health, and payment data lives, then tags each column. Masking and subsetting rules are built from that map, so nothing sensitive is copied by accident.
Data masking
Data masking replaces or hides sensitive values in non-production data while keeping the format, so applications and tests still work. Masking is not the same as encryption: masked data is usually not meant to be reversed, while encrypted data can be decrypted by anyone with the key.
Example: in a customer table, "Maria Lopez, maria.lopez@example.com" becomes "Anna Berg, anna.berg@test.example", and the same customer gets the same fake name in the orders and support databases.
Protection technique | What it does | Example | When to use it |
|---|---|---|---|
Substitution | Replaces real values with realistic fictional ones | Real names replaced with generated names | Names, addresses, and emails in UI and regression tests |
Shuffling | Reorders values within a column to break the link to a person | Salaries shuffled between employee records | Analytics or reports that need realistic distributions |
Encryption | Turns values into ciphertext that only key holders can read | Bank account numbers encrypted in an export file | Data that authorized users must be able to restore |
Tokenization | Replaces values with tokens that map back in a secure vault | Social Security numbers replaced with tokens such as Token123 | Payment and identity data |
Character masking | Hides part of a value | All but the last 4 digits of an SSN hidden (XXX-XX-1234) | Values that people need to recognize but not read in full |
Dynamic data masking | Masks values at query time based on the user's role | Salary hidden in results for users without finance access | Production or production-support access, not test copies: the real values stay stored, so test environments still hold sensitive data |
Randomization | Changes values within a set range | Salaries adjusted by a random amount within 10% | Numeric fields in reports and analytics tests that need realistic ranges |
Encryption and tokenization are reversible, so they protect data rather than mask it; use them when authorized users must restore the original value.
Static masking changes a copy of the data once, before it reaches the test environment. Dynamic masking leaves the stored data as it is and hides values when someone reads them. For test environments, prefer static masking, because dynamic masking leaves the real data in place.
Data subsetting
Data subsetting creates a smaller, representative slice of a production database. Good subsetting follows foreign keys, so each customer arrives with their orders, addresses, and payments.
Example: instead of copying 2 million customers, you extract 1,000 customers from 5 countries with all their related records, then mask them.
Benefits:
- Smaller data volumes, so environments are cheaper and faster to refresh.
- Relationships between records stay intact.
- You choose what to include, such as one region or a set of account types.
Synthetic data generation
Synthetic data generation creates artificial data that follows the structure, rules, and patterns of real data without containing real records. There are 3 common approaches:
- Rule-based: you define formats and rules, such as "postal code matches the country" or "order date after sign-up date".
- Statistical: values follow distributions measured on real data, such as order sizes or ages.
- AI-based: a model learns patterns from a source data set and generates new records. Run it on data that is already masked or approved for that use.
Example: to test a new loyalty tier, you generate 200 customers with spend just below, at, and just above the tier threshold, because production has none yet.
Synthetic data is a good fit when there is no production data yet, when you need rare edge cases, or when data has to leave the company. Its limit is realism: it only covers the cases your rules or models describe. For a walkthrough, see synthetic test data generation.
Data virtualization and cloning
Data virtualization gives each test environment a lightweight virtual copy of a database instead of a full physical copy. You can bookmark a known state, reset to it after a run, and give several teams their own copy at the same time. A gold copy is the known-good, versioned baseline that environments are refreshed or reset from.
Example: the regression suite runs against a virtual clone of the masked gold copy, and the clone is reset to the bookmark before the next run.
Data refresh and reservation
Refresh brings test data back to a known state on a schedule or after a run. Reservation lets a tester or a test job book specific records, so 2 tests don't change the same account at the same time.
Example: each nightly regression run reserves 20 customer accounts, uses them, and releases them; the environment is refreshed from the gold copy every Sunday.
Which technique fits which test
Test type | Usual data source | Why |
|---|---|---|
Unit tests | Hand-crafted fixtures | Small, fast, and fully under the developer's control |
API tests | Synthetic data or data generated on the fly | Easy to create in any volume and reset per run |
UI regression | Masked subset or virtual clone | Realistic data with stable relationships |
Performance tests | Synthetic or randomized volume data | Production-like volume without real people |
User acceptance testing | Masked subset | Business users recognize realistic records |
Demos and training | Synthetic data | No real customer records leave the company |
Most teams combine techniques: a masked subset as the gold copy, plus synthetic rows for edge cases, plus data that tests create and clean up themselves. Keep each test environment paired with the data set it should hold.
The test data management process
- Define data needs. For each test case, list the accounts, states, volumes, and edge cases it needs. Start from your test cases and requirements, not from the database.
- Discover and classify sensitive data. Find where personal, health, and payment data lives in each source system before you copy anything.
- Choose a source for each need. Decide whether each need is met by a subset, masked data, synthetic data, a virtual clone, hand-crafted records, or data the test creates itself.
- Prepare and provision. Mask, subset, or generate the data, then deliver it to the test environment through a self-service request or a pipeline step.
- Use and isolate. Give each test or run its own records, or reserve them, so tests don't collide.
- Refresh, reset, or retire. Reset environments to the gold copy after runs, refresh on a schedule, and delete data sets that are no longer used.
- Govern and audit. Control who can request which data, log access, and set retention rules for test copies.
How to build a test data management strategy
A TDM strategy, sometimes called a test data management framework, is the set of rules your team follows for test data across releases. It belongs next to your test strategy, and each release's test plan applies it.
- Name an owner. One person or team owns test data sources, masking rules, and refresh schedules.
- Set a request model. Agree what a data request contains: environment, data entity, volume, masking level, and the date it's needed.
- Map data sets to environments. Decide which environments get masked subsets, which get synthetic data, and which get virtual clones.
- Set a refresh cadence. For example, nightly for CI environments and once per release for UAT.
- Version data definitions. Keep fixtures, generation rules, and masking rules in version control with the test code.
- Keep secrets out of data files. Store passwords, API keys, and tokens in a secrets store or protected variables, not in spreadsheets.
- Write down data assumptions. Each test case should say which data it expects and whether it changes that data.
Track a few metrics to see whether the strategy works:
- Time from data request to data ready
- Share of test failures caused by data rather than code
- Edge cases covered by available data
- How often each environment is refreshed
Test data management best practices
- Start from the tests, not the database. List what each test needs before you copy anything.
- Mask before data leaves production. Treat unmasked copies in test environments as a privacy incident waiting to happen.
- Keep masking consistent. The same person should get the same fake values in every system, so joins and end-to-end tests still work.
- Prefer small data sets. A referentially intact subset is faster to load, refresh, and debug than a full copy.
- Give tests their own data. Create data at runtime or reserve it, and reset after each run.
- Keep a gold copy. Version a known-good baseline and reset environments to it.
- Review data with test changes. When a feature or schema changes, update the data in the same change.
Test data management in test automation and CI/CD
Automated tests run often, in parallel, and without anyone watching, so test data problems show up there first.
- Feed data into tests. Data-driven testing separates test logic from test data, so one test runs against many rows from a file or a database query.
- Use variables per environment. Keep URLs and account names in environment profiles, and passwords in protected variables or a secrets store, so the same suite runs on dev, QA, and staging.
- Provision per pipeline run. Create or reserve the data at the start of the run and clean it up or reset it at the end.
- Generate data at runtime when you can. Tests that create their own unique data are less likely to break when shared data changes. This video shows how to generate test data at runtime.
Data-related flaky tests and how to fix them
Cause | What you see | Fix |
|---|---|---|
Shared accounts | A test passes alone and fails in the suite | Unique data per run, or reservation |
Stale data | Tests fail after a refresh or a schema change | Refresh on a schedule, or create data at runtime |
Order dependence | A test only passes after another one runs | Independent setup and teardown for each test |
Parallel collisions | Random failures when jobs run at the same time | Separate data per worker, or reservation |
Test data compliance: GDPR, HIPAA, CCPA, and PCI DSS
This section is practical guidance, not legal advice. Check your obligations with your privacy or legal team.
Regulation | What it covers | What it means for test data |
|---|---|---|
GDPR | Personal data of people in the EU and EEA | Pseudonymized data is still personal data; anonymized data is not. Mask or synthesize before data leaves production, and limit who can access test copies |
HIPAA | Protected health information held by US covered entities and their business associates | De-identify health data before it reaches test environments, or treat those environments with production-level safeguards |
CCPA and CPRA | Personal information of California residents | De-identified data falls outside most obligations if you keep it de-identified; raw copies carry the same duties as production |
PCI DSS | Cardholder data such as card numbers | Keep live card numbers out of test environments; use your payment provider's test cards and sandbox tokens |
4 practices cover most of it:
- Minimize. Copy only the fields a test needs.
- Anonymize or pseudonymize on purpose. Know which one you're doing, because the rules differ.
- Control access. Apply role-based access to non-production environments that hold real or masked data.
- Set retention. Delete test copies on a schedule and log when you do.
Example: test data for an online store's checkout release
This example follows the same fictional online store as our test plan example. Release 4.2 replaces the 3-step checkout with a single-page checkout and lets signed-in shoppers save a card. All names and numbers are illustrative.
Test need | Data source | How it's prepared |
|---|---|---|
Saved cards: add, choose, and remove a card | Payment provider's published test cards and sandbox tokens | No real card numbers; the store keeps only the token and the last 4 digits, as in production |
Returning customers with order history | Masked subset of production customers | 500 customers with their addresses and orders; names, emails, and phone numbers substituted consistently across the orders and email systems |
Guest checkout | Data generated on the fly | Each automated run creates a unique guest email in the test inbox and deletes the order afterward |
Promo codes and gift cards | Hand-crafted records | An expired code, a code at its usage limit, and a gift card with a balance lower than the order total |
Edge cases | Synthetic data | Long names, accented and right-to-left characters, addresses in every supported country, and carts with 1 and 50 items |
Regression runs in CI | Virtual clone of the masked gold copy | Reset to the bookmark before every run; parallel jobs reserve separate customer accounts |
The test plan's entry criteria include "test data and payment sandbox accounts ready", so this data set is part of the go or no-go for starting testing. The test report for the same release then shows whether any failures traced back to data.
Test data management tools and software
Test data management tools (also sold as TDM software or platforms) find sensitive data, then mask, subset, generate, or virtualize it and deliver it to test environments. Options include Broadcom Test Data Manager, Perforce Delphix, K2view, IBM Optim, and Tonic Structural, plus open-source Jailer and Faker for small teams.
How to choose a test data management tool
- Technique coverage: which of masking, subsetting, synthetic generation, and virtualization you need.
- Data sources: the databases, files, mainframe, and SaaS systems the tool connects to.
- Deployment: on-premises, cloud, or inside your own environment.
- Referential integrity: whether masking and subsetting keep relationships across systems.
- Self-service and CI/CD: whether testers and pipelines can request data without a ticket.
- Compliance reporting: whether it can show where sensitive data is and how it was masked.
The table below is based on each vendor's own product page, as of November 2026. "Not stated" means the vendor's page doesn't say.
Tool | Type | Main techniques | Deployment (vendor stated) | Public pricing |
|---|---|---|---|---|
Broadcom Test Data Manager | Enterprise TDM | Discovery, masking, synthetic, virtual clones, reservation | Not stated | On request |
Curiosity Software Enterprise Test Data | TDM with model-based generation | Discovery, masking, synthetic, self-service provisioning | Not stated | Not published |
DATPROF | TDM platform | Masking, synthetic, subsetting, self-service portal | Not stated | Not published |
Enov8 Test Data Manager | Masking, compliance, and data booking | Discovery, masking, booking and refresh, subset and synthetic options | Not stated | Not published |
GenRocket | Synthetic data generation | Rule- and scenario-based synthetic data, provisioning | Not stated | Not published |
IBM Optim Test Data Management | Enterprise TDM | Subsetting, masking, provisioning | Not stated | Not published |
K2view Test Data Management | Entity-based TDM | Subsetting, masking, synthetic, self-service provisioning | On-premises, cloud, and hybrid | Not published |
Mage Data | Data security platform with a TDM module | Discovery, static and dynamic masking, subsetting, virtualization | Not stated | Not published |
Perforce Delphix | Virtualization, masking, and synthetic data | Virtualization, discovery and masking, synthetic | On-premises, cloud, hybrid, and multicloud | Not published |
Synthesized | TDM for SAP, databases, and documents | Masking, subsetting, generation | Inside the customer's environment | Not published |
Tonic Structural | Masking, synthesis, and subsetting | Discovery, masking, synthesis, subsetting | Self-hosted or Tonic Cloud | Not published |
Jailer | Open-source subsetting | Subsetting, data browsing | Desktop tool, any JDBC database | Free, open source |
Faker | Open-source Python library | Synthetic data | Python library | Free, MIT License |
Broadcom Test Data Manager
Broadcom Test Data Manager is an enterprise TDM product. Broadcom lists PII discovery and format-preserving masking, synthetic data that keeps relationships, a Database Virtualization Engine (DAVE) for virtual clones you can snapshot and roll back, and a self-service portal for finding, reserving, and provisioning data. It also lists mainframe masking for DB2, IMS, and VSAM on z/OS, and privacy audit reports for GDPR, HIPAA, and CCPA. Pricing is on request.
Curiosity Software Enterprise Test Data
Curiosity Software's Enterprise Test Data covers data discovery, masking before provisioning, synthetic data designed from visual models, and self-service provisioning forms.
DATPROF
DATPROF offers masking, synthetic test data generation, subsetting, and test data automation in CI/CD pipelines, with a self-service portal for requesting and refreshing data.
Enov8 Test Data Manager
Enov8 Test Data Manager finds personal data, including in free-text columns, and applies non-reversible masking that stays consistent across systems. It follows a profile, mask, and validate workflow, and lets teams book and refresh test data.
GenRocket
GenRocket focuses on synthetic data: teams define the structure, rules, and scenarios they need and generate data on demand in any volume or format, without copying production. It also offers subsetting in which PII is replaced with synthetic values.
IBM Optim Test Data Management
IBM Optim Test Data Management provisions right-sized, production-like data sets as complete business objects with referential integrity. IBM lists a central policy-driven masking engine, scenario-specific data sets, reusable self-service workflows, and CI/CD integration.
K2view Test Data Management
K2view organizes test data into business entities, such as a customer, account, or order, and provisions them with referential integrity. It covers subsetting in business terms, masking that stays consistent across systems, synthetic generation, and self-service provisioning.
Mage Data
Mage Data is a data security platform that covers sensitive data discovery and dynamic masking. Its TDM module combines static masking, subsetting, and database virtualization for CI/CD.
Perforce Delphix
Perforce Delphix delivers virtualized, masked, or synthetic test data to developers, testers, and pipelines. Delphix Continuous Compliance discovers and masks sensitive data, and Delphix Synthetic Data generates test data.
Synthesized
Synthesized builds linked, privacy-safe test data from SAP systems, databases, and documents, and runs inside the customer's environment. It lists policy-based masking mapped to GDPR, DORA, and HIPAA, plus subsetting, generation, and refresh from CI/CD.
Tonic Structural
Tonic Structural provisions de-identified, production-like test data. It lists PII and PHI discovery with custom rules, masking and synthesis that keep relationships, subsetting with referential integrity, and connectors for relational and NoSQL databases, data warehouses, and files. It runs self-hosted or in Tonic Cloud.
Open-source options: Jailer and Faker
Small teams can start without a TDM platform. Jailer extracts consistent subsets of a database by following foreign keys or relationships you define, and works with any database that has a JDBC driver. Faker is a Python library, under the MIT License, that generates fake names, addresses, and other values in many locales. A simple starter path: Jailer for a small subset, a masking script, Faker for edge-case rows, and CSV or database files that your tests read.
Where Katalon fits
Katalon is not a test data management platform. It doesn't mask, subset, or virtualize test databases. TDM platforms produce safe data; the Katalon True uses that data in tests. In Katalon Studio, tests read Excel, CSV, database, or internal data files through data binding and use execution profiles and protected variables per environment, and Katalon TestOps adds a Test Data field to manual test steps.
For how to set these up, see test data management in Katalon.
Frequently asked questions
TDM stands for test data management: the practice of preparing, protecting, and delivering the data that tests need outside production, so each test gets relevant data without exposing real customer records.
A test data management tool finds sensitive data and then masks, subsets, generates, or virtualizes it, and delivers it to test environments on request or from a pipeline. Examples include Broadcom Test Data Manager, Perforce Delphix, K2view, IBM Optim Test Data Management, and Tonic Structural, plus open-source tools such as Jailer and Faker.
Data masking is one technique within test data management. TDM also covers deciding which data each test needs, sourcing it, subsetting, synthetic generation, provisioning, refresh, and governance.
Raw production data brings privacy, compliance, and stability risks, because test environments usually have weaker controls than production. Mask or anonymize it first, copy only the fields tests need, and limit who can access it.
Masked data keeps the shape and relationships of real data, which suits regression and acceptance testing. Synthetic data contains no real records and can cover edge cases production doesn't have. Many teams use a masked subset as the baseline and add synthetic rows for edge cases.
Test data generation creates new data, usually synthetic. Test data management is the wider practice that also covers sourcing, masking, provisioning, refresh, and governance of all test data, generated or not.
A gold copy is a known-good, versioned baseline data set. Test environments are refreshed or reset from it, so every run starts from the same state.
Refresh CI environments as often as tests change data, often nightly or per run, and UAT environments once per release. Reset to a versioned gold copy, so every run starts from the same known state.





Test everything. Ship with confidence.
From generating test cases to spotting failures, Katalon's AI works across your entire pipeline, automatically.
