Let resource constraints shape the plan: on a tight timeline, use Pairwise or Equivalence Class Partitioning to cut test volume first, and on a high-risk system, add Boundary Value Analysis for edge coverage.
Match the technique to the input: Equivalence Class Partitioning and Boundary Value Analysis for value ranges, Decision Tables for complex business rules, and Pairwise Testing for many configurable parameters.
For a password field that accepts 8 to 20 characters, equivalence classes need only three test cases (valid, too short, too long), and Boundary Value Analysis adds six edge values: 7, 8, 9, 19, 20, and 21 characters.
Pairwise testing makes sure every pair of parameter values is tested at least once. For 4 browsers, 3 operating systems, 3 payment methods, and 3 user types, that cuts 108 full combinations to around 10 to 20 test cases.
For white-box systems, Cyclomatic Complexity (Edges minus Nodes plus 2) gives the number of linearly independent paths, and structured testing creates one test case for each basis path.
The first step is often the hardest, and in software quality engineering, this is especially true. When presented with a system, how do you go about and decide what to test? Standing in the middle of the unknown, we need guidance, and learning about test case design techniques is a good place to start. As software complexity scales with AI-integrated features, these techniques ensure your coverage is both deep and efficient.
In this article, we’ll show you:
2 types of software system: black-box and white-box, each requiring a unique approach to test case design
Techniques to design test case for each system
Best practices for each types of system
Let’s dive in!
Black-box System vs White-box System
To design a test case, you first need to consider the opacity of the system.
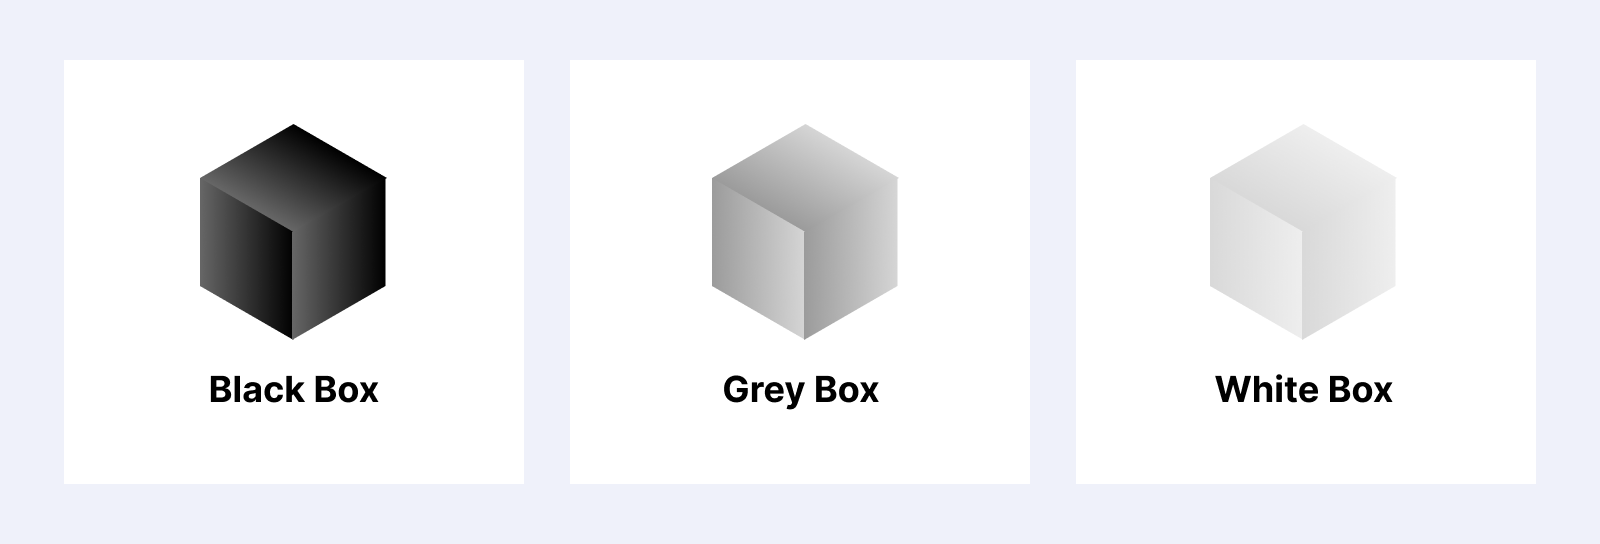
At one end of the spectrum, we have a black-box system. Testers don’t know its internal code structure or internal mechanism. All they know is what the system can accomplish and what we can put in it. To an end-user without technical knowledge, the system is a black box. If you are working with a system where the internal code is hidden, you are performing black box testing.
At the other end of the spectrum, we have a white-box system. Testers have full knowledge of its internal code structure.
In the middle we have the gray box. Testers have partial knowledge of the internal code structure. In practice, most systems in real-world applications can be considered a “gray box”.
For example, simply by navigating to any random website and using its features, you are interacting with a black-box system. However, as soon as you right-click on a blank space on the screen and choose Inspect, you’ll get to see the HTML code behind it. The website is now a gray box to you.
To the web developers behind the website, it is a white box, since they have full access to the source code.
Modern quality engineering has evolved. According to IBM, adopting a "Shift-Left" mindset, where testing design starts during the requirements phase, can prevent defects that cost 15x more to fix if caught after release.
How to Choose the Right Test Case Design Technique
Knowing the techniques is only half the challenge, the other half is knowing which one to reach for. Use this three-step framework before you start designing any test suite.
Tight timeline? Prioritize Pairwise or Equivalence Class Partitioning to cut test volume first.
High-risk system? Layer Boundary Value Analysis on top of equivalence classes for edge coverage.
Complex conditional logic? Decision Tables give you full traceability from requirements to test cases.
Code quality review needed? Cyclomatic Complexity tells you where white-box effort should be concentrated.
Test Case Design Techniques For Black-box System
The following techniques apply when you have no access to the system's internal code: you are testing from the outside, based on inputs and expected outputs. For full definitions, worked examples, best practices, and edge cases for each technique, see the Black Box Testing: Complete Guide.
1. Equivalence Class Testing
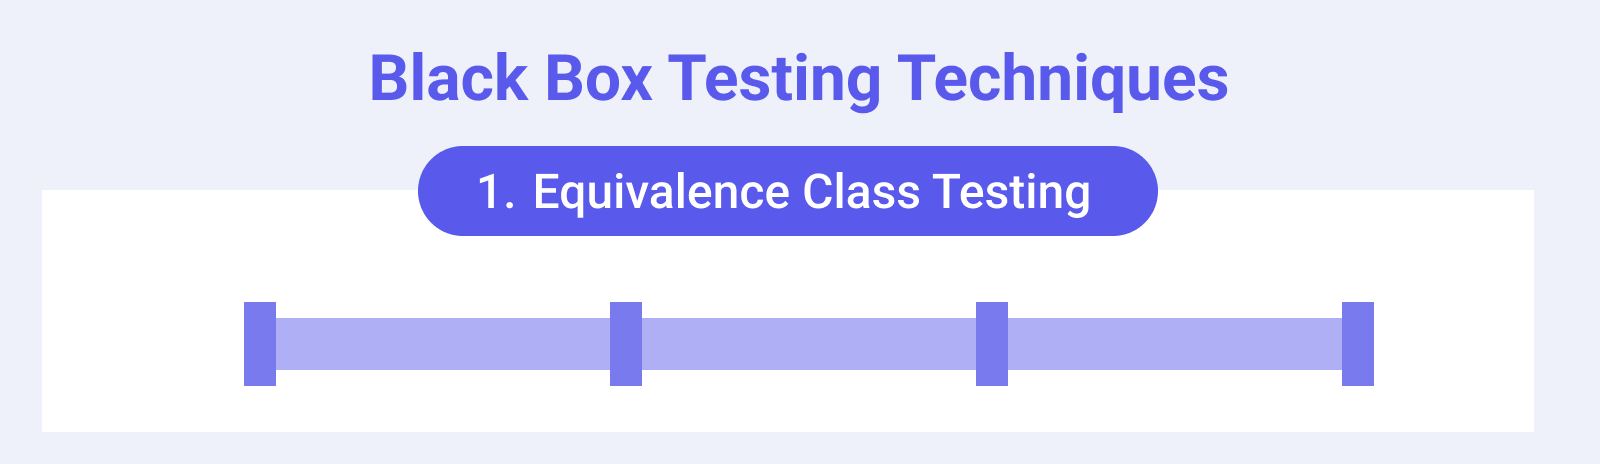
Equivalence Class Testing, also called Equivalence Partitioning, is a black-box testing technique designed to minimize the number of test cases while ensuring adequate coverage.
In this method, input data is divided into equivalence classes or partitions. Each class represents a group of inputs that the system should handle in the same way.
From each equivalence class, one or more representative values are selected for testing. These values are expected to produce the same result as any other value in the same class, reducing the need to test every possible input.
There are typically two types of equivalence classes:
Valid Equivalence Class: Inputs that the system should accept and process correctly.
Invalid Equivalence Class: Inputs that the system should reject or handle differently.
For example, a password field requiring 8–20 characters gives you three classes: valid (8–20 chars, e.g. "Pa55word!"), too short (<8 chars, e.g. "abc"), and too long (>20 chars, e.g. "thispasswordistoolong123"). One representative from each class, three test cases instead of hundreds.
An equivalence class is only as good as its predictability. If one input in the group uncovers a bug (or passes), its counterparts will likely do the same. This means you only need one representative test case per class, allowing you to cut your test suite size without sacrificing coverage.
Best for: numeric ranges, date fields, string length constraints, enumerated types, any input domain with clear valid/invalid boundaries.
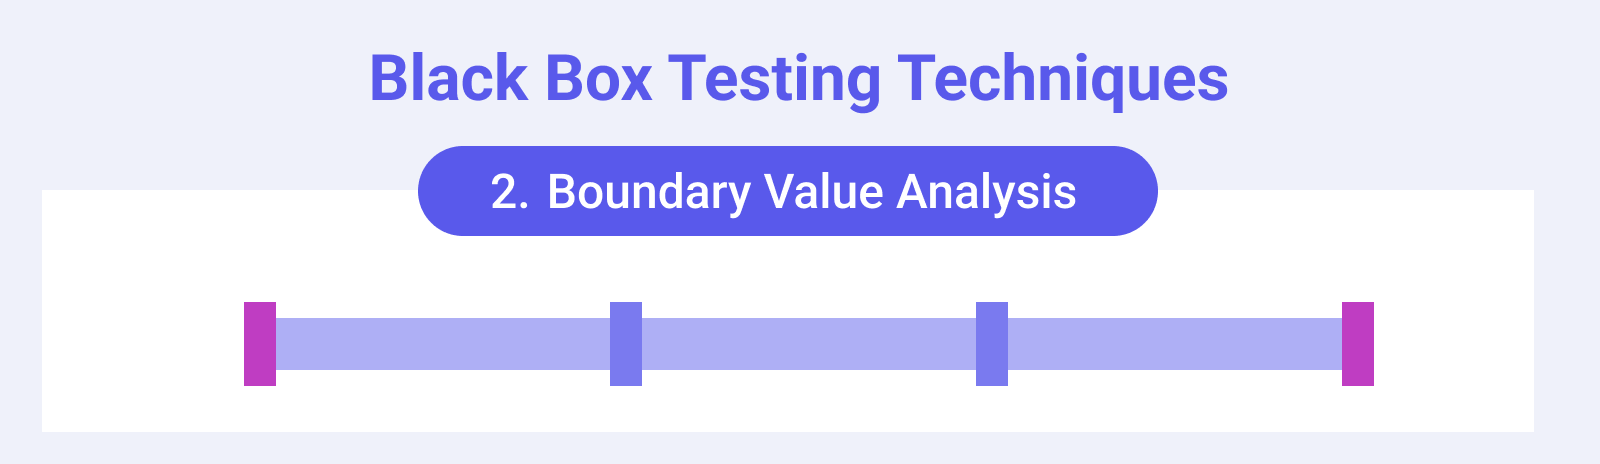
Boundary value analysis is an extension of equivalence partitioning testing, with a focus on the boundaries between equivalence classes. The core idea is that errors are more likely to occur at the edges of input ranges rather than in the middle, making boundary testing crucial.
Building on the password field example: a field accepting 8–20 characters has two boundaries. BVA produces test cases at the 6 most critical values: just below the lower boundary (7 chars), at the lower boundary (8 chars), just above (9 chars), just below the upper boundary (19 chars), at the upper boundary (20 chars), and just above (21 chars). These six values are where off-by-one errors, fence-post bugs, and boundary logic failures are most likely to hide.
Best for: any system with defined minimum and maximum input limits — always pair with Equivalence Class Partitioning for complete input coverage.
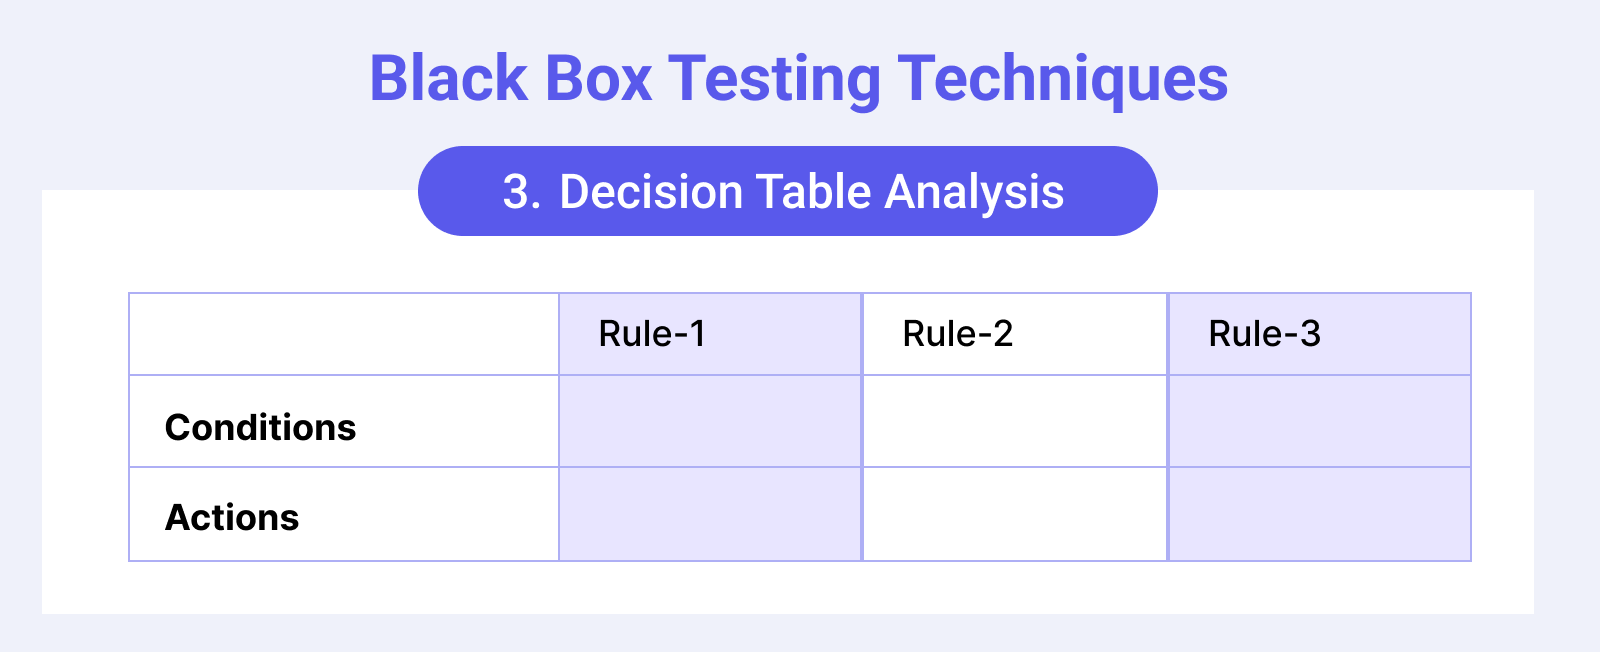
Decision Table Testing is a black-box testing technique that uses a decision table to map various input combinations to their corresponding outputs.
Key concepts of a decision table include:
Condition: Input variables that influence system behavior
Action: Outcomes based on combinations of conditions
Rule: A specific combination of conditions and their resulting actions
Rule-1
Rule-2
[...]
Rule-p
Conditions
Condition-1
Condition-2
...
Condition-m
Actions
Action-1
Action-2
...
Action-n
Consider an e-commerce discount system with two conditions: membership status (Member/ Guest) and cart value (above or below $50). This produces four rules: four distinct test cases - each mapping a condition combination to its expected discount outcome. Each rule column is one test case, and the table makes it immediately visible if any combination has been missed.
Decision table testing is particularly useful for systems implementing complex business rules that can be represented as combinations of conditions.
Best for: eligibility logic, pricing engines, access control rules, any system where multiple conditions combine to determine an outcome.
Pairwise testing is a black-box testing technique that focuses on testing combinations of two inputs at a time. Instead of testing every possible combination, this method helps reduce the number of tests while still providing good coverage.
Testing every combination of OS, browser, and network is physically impossible for rapid release cycles. Gartner predicts that by 2027, 80% of enterprises will integrate AI-augmented testing tools to automate complex tasks like pairwise optimization, helping teams move from simple execution to strategic orchestration.
Let's look at a brief case study to illustrate the effectiveness of pairwise testing: a software company is developing a new e-commerce platform. The platform needs to be tested across different browsers, operating systems, payment methods, and user types, such as:
Browser: Chrome, Firefox, Safari, Edge
Operating System: Windows, macOS, Linux
Payment Method: Credit Card, PayPal, Bank Transfer
User Type: New User, Returning User, Guest
Testing all possible combinations would require:
4 (Browsers) x 3 (Operating Systems) x 3 (Payment Methods) x 3 (User Types) = 108 test cases
By using a pairwise testing tool (such as PICT or ACTS), you can generate a smaller set of test cases that ensure every pair of parameter values is tested at least once. This typically reduces the number of test cases to around 10-20, depending on the specific parameters and values.
Test Case Design Techniques For White-box System
White-box techniques apply when you have access to the system's internal code and want to validate execution paths, branch logic, and code structure, not just observable behavior.
1. Control Flow Testing
Control flow testing is a white-box testing technique that emphasizes creating and executing test cases to cover predetermined execution paths within the program's code.
While control flow testing provides a high level of thoroughness, it also presents some challenges:
Path Explosion: The number of possible paths can become immense. Modern applications are typically so complex that testing every possible control flow path exhaustively becomes practically impossible.
Implemented Paths Only: White-box testing only works with paths that have been implemented. If a particular path is missing, it won’t be detected. For instance, in the following code, there is no path for scores below 60:
Logical Errors Despite Correct Flow: Even when the flow is correct, there can still be logic errors. In this example, the flow is correct, but the inventory should decrease (-1) rather than increase (+1) when an order is dispatched:
PythonCopy
def calculate_inventory(order_dispatched, current_inventory): if order_dispatched return current_inventory + 1
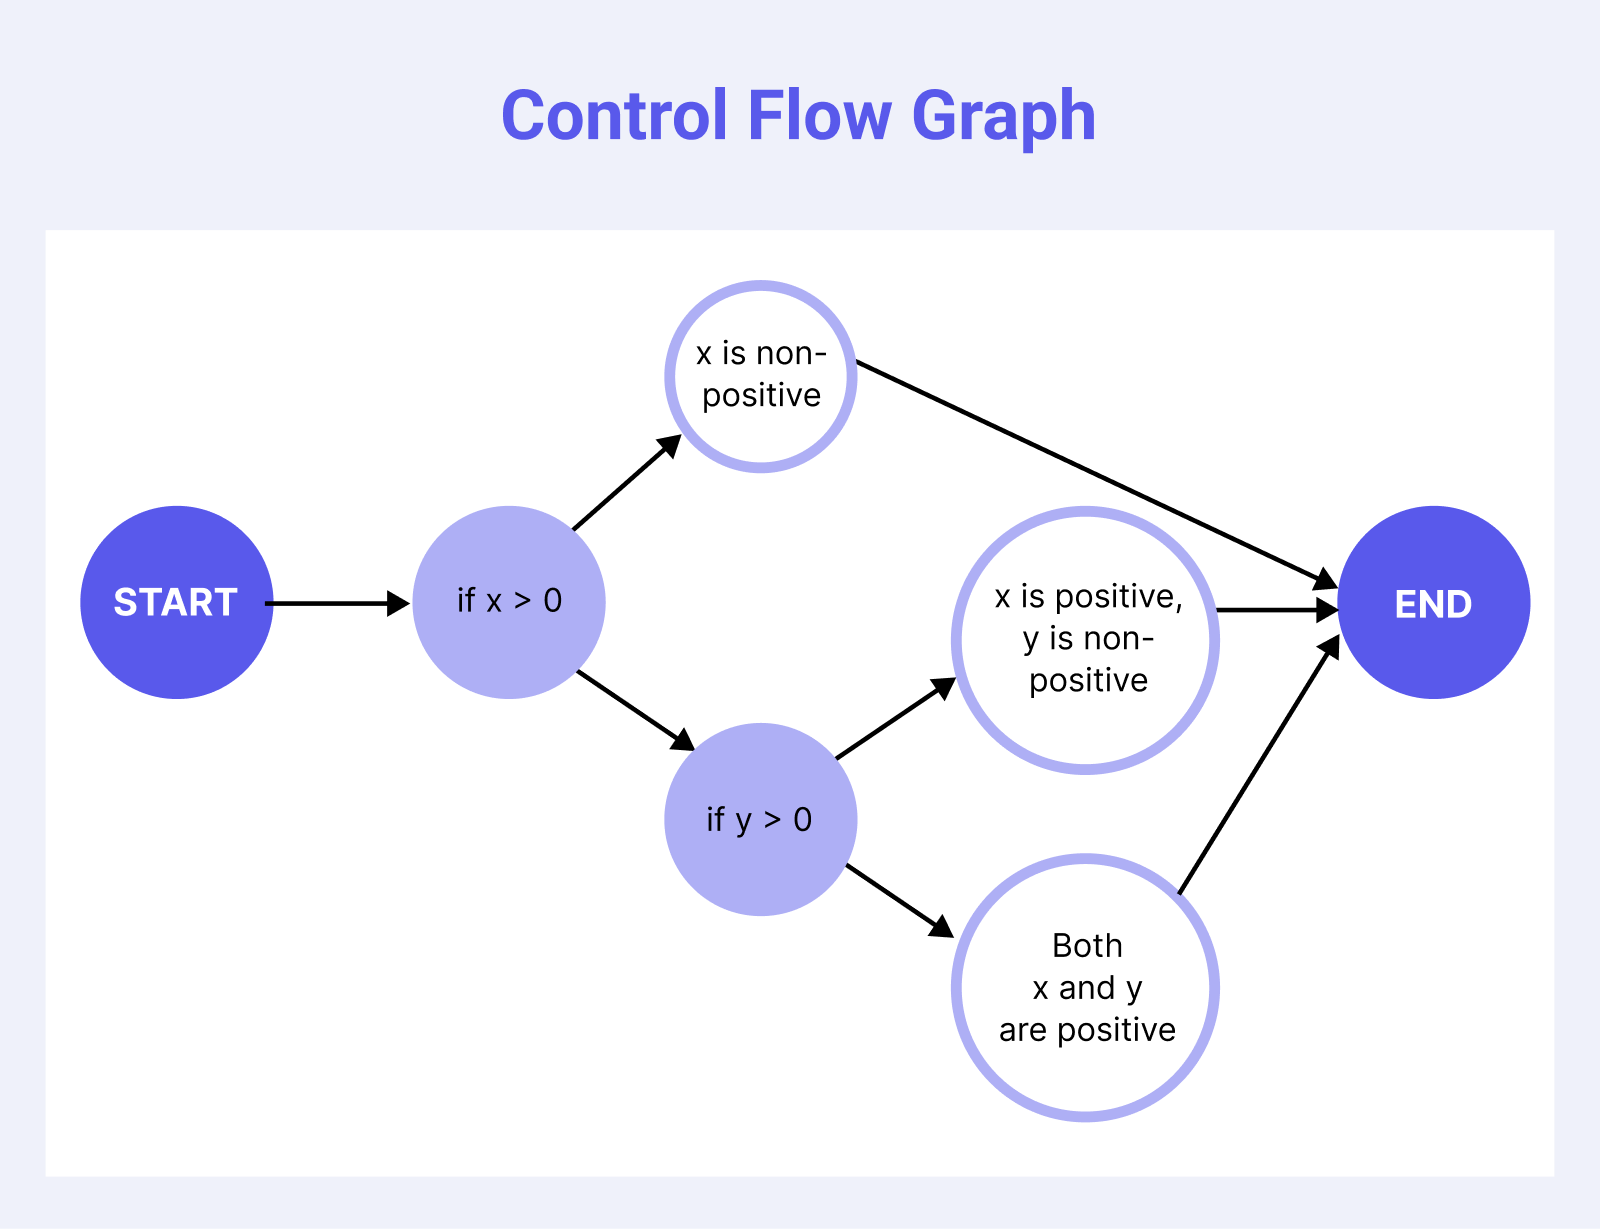
To perform control flow testing, it’s important to understand the Control Flow Graph (CFG). A CFG visually represents all possible paths a program might take during execution and is widely used in control flow testing to analyze and understand the program’s structure.
A control flow graph consists of three main components:
1. Node: Represents individual statements or blocks of code. For example, the following snippet has three nodes:
PythonCopy
int a = 0; // Node 1 if (b > 0) { // Node 2 a = b; // Node 3 }
2. Edge: Represents the flow of control between nodes, indicating the program's execution path. There are two types of edges:
Unconditional edge: Direct flow from one statement to another.
Conditional edge: A branch based on conditions (e.g., True/False results from an if-statement). In the snippet above, there’s a conditional edge from the if (b > 0) statement to a = b.
3. Entry/Exit Points: These are the start and end points of a program in the CFG.
Let's take a look at this example:
PythonCopy
void exampleFunction(int x, int y) { if (x > 0) { if (y > 0) { printf("Both x and y are positive.\n"); } else { printf("x is positive, y is non-positive.\n"); } } else { printf("x is non-positive.\n"); } }
Here we have 7 nodes: 1 entry point, 1 exit point, 5 decision points.
1: Entry point of exampleFunction.
2: if (x > 0).
3: if (y > 0).
4: printf("Both x and y are positive.").
5: printf("x is positive, y is non-positive.").
6: printf("x is non-positive.").
7: Exit point of exampleFunction.
Edges:
(1 -> 2)
(2 -> 3) if x > 0
(2 -> 6) if x <= 0
(3 -> 4) if y > 0
(3 -> 5) if y <= 0
(4 -> 7)
(5 -> 7)
(6 -> 7)
In this CFG, there are three possible execution paths to cover all outcomes.
2. Structured Testing (Basic Path Testing)
Structured testing, also known as basic path testing, is a white-box testing technique that focuses on identifying and testing all independent paths within the software. The aim is to ensure that every possible execution path in a program is tested at least once.
A typical structured testing process follows these steps:
Derive the control flow graph from the software module.
Calculate the graph's Cyclomatic Complexity (C).
Select a set of C basis paths.
Create a test case for each basis path.
Execute the test cases.
Cyclomatic Complexity is a software metric used to measure the complexity of a program's control flow. It was introduced by Thomas J. McCabe, Sr. in 1976 and serves as a key indicator of the number of linearly independent paths through a program's source code. The formula is:
C = Edges - Nodes + 2Let's take a look at this Control Flow Graph:
There are in total 8 edges and 7 nodes, so the Cyclomatic Complexity would be:
C = 8 - 7 + 2 = 3
This means there are 3 linearly independent paths through the program.
Here's how you interpret the C metric:
C = 1-10: Simple program, low risk, easy to test and maintain.
C = 11-20: Moderate complexity, requiring more detailed testing and review.
C = 21-50: High complexity, increased risk of errors, requiring extensive testing and documentation.
C > 50: Very high complexity, difficult to test and maintain, likely in need of refactoring.
Based on the identified paths, we can create the following test cases:
Test Case 1:
Inputs: x = 5, y = 2
Expected Output: Both x and y are positive.
Test Case 2:
Inputs: x = 5, y = -2
Expected Output: x is positive, y is non-positive.
Test Case 3:
Inputs: x = -2
Expected Output: x is non-positive.
Each test case above pairs specific inputs with an expected output. For the steps, preconditions, and format that make a test case easy for someone else to run, see our guide on how to write test cases.
Conclusion
Modern test case design techniques are the backbone of effective software testing. They help us go beyond just "checking the boxes" and ensure we’re really digging into the areas where bugs might hide. By balancing classic logic with AI-optimized tools and Shift-Left strategies, you'll deliver faster, higher-quality releases.
Remember the three-step framework: determine system opacity first, then match the technique to your input type, then factor in resource constraints. For deep dives into any of the black-box techniques covered here, start with the Black Box Testing: Complete Guide — and for ECP specifically, the Equivalence Class Partitioning: A Complete Guide.
Frequently asked questions
Black-box design focuses on external behavior (inputs/outputs without knowing internals), while white-box design targets internal code structure and execution paths using code-aware techniques.
Start by determining system opacity: no code access means black-box techniques; full code access means white-box; partial access means combine both. Then match the technique to your input type, ranges suggest ECP and BVA, complex business rules suggest Decision Tables, many parameter combinations suggest Pairwise, and code paths suggest Control Flow or Structured Testing. See the decision framework above for a full breakdown.
It groups inputs into valid/invalid equivalence classes where values should behave the same, then tests representative values per class—cutting redundant cases while keeping solid coverage.
BVA is an extension of equivalence partitioning that tests edge values (just below/at/just above boundaries) because defects are more likely at input range limits than in the middle.
Use Decision Tables when you have business rules driven by combinations of conditions and actions (each rule becomes a test). Use Pairwise when many parameters create combinatorial explosion and you want coverage of all pairs with far fewer tests.
They verify execution paths using a Control Flow Graph (nodes/edges/branches); Structured Testing uses Cyclomatic Complexity (Edges − Nodes + 2) to determine how many independent paths to cover with test cases.
Cyclomatic Complexity (C = Edges - Nodes + 2) measures the number of linearly independent paths through a program. A C of 1–10 indicates a simple program; 11–20 moderate complexity; 21–50 high complexity; above 50 suggests the code likely needs refactoring. It tells you the minimum number of test cases required for full independent path coverage.
Shift-Left testing means starting test design earlier in the development cycle — during requirements or design phases rather than after development. This allows teams to apply techniques like Equivalence Class Partitioning from API specs before any code is written, catching defects that cost up to 15x more to fix if found post-release.
Huyen Nguyen is an experienced technical writer in the software testing industry. With strong technical expertise and a deep understanding of Katalon products, she creates clear, practical guides that support testers at every skill level.
See how Katalon fits the way your team tests.Book a demo of Studio, TestOps or all of Katalon True, built around the apps and workflows you test today.