


What test case management is, what a test case management system does, when to move off spreadsheets, the 6-step process, how to organize test cases, which metrics matter, and best practices.
A test suite stops being useful when nobody trusts it: duplicate cases, steps that no longer match the product, and results split between a spreadsheet and CI logs. Test case management is the work that keeps test cases current, findable, and tied to what they check.
This guide covers what test case management is, what a test case management system does, when to move off spreadsheets, the 6-step process, how to organize and measure test cases, and best practices. It uses one running example: an online store's regression suite of 200 test cases covering sign-in, checkout and payment, and search.
What is test case management?
Test case management (TCM) is the process of creating, organizing, executing, tracking, and maintaining test cases across the software testing life cycle. It keeps every case findable, current, and linked to the requirement it checks and the results it produced, so the team knows what has been tested, what passed, and what needs updating.
A test case management system (TCMS) is the software that holds this work: a central test case repository, version history, execution status and history, requirement traceability, and reports.
Test case management sits between 2 related topics, test management and writing test cases:
- Test management decides what runs, when, and whether the release is ready.
- Test case management keeps the test cases and their results complete and current.
- Writing test cases is the craft of making a single case clear and repeatable (how to write test cases).
Why test case management matters
Without it, test cases drift. They pile up in personal files, copies diverge, and nobody can say which version ran last week. With it, the team gets 5 things:
- One source of truth: every tester runs the current version of each case, and duplicates are easy to spot.
- Coverage you can show: each requirement links to the cases that check it, so gaps are visible before release, not after.
- Faster triage: a failed case links to its requirement and its defect, so developers know what broke and what it affects.
- Less rework: cases written once are reused across releases and suites instead of rewritten.
- An audit trail: who changed a case, when, and which version ran, which regulated teams need and other teams use when a result is questioned.
For the online store, that means the 40 payment cases in the regression suite are the same 40 cases each tester runs, each one linked to a checkout requirement, with every past result attached.
What a test case management system does
Most test case management systems cover the same core functions. Tools differ in depth, but these are the capabilities to expect:
- Central repository: test cases live in one place, in folders and suites, with fields such as priority, owner, tags, and custom fields.
- Versions and history: each change to a case is recorded, so you can see who changed what and which version a run used.
- Linkage to requirements and defects: each case links to the user story or requirement it checks and to the defects it found. A requirements traceability matrix is the document version of the same idea.
- Execution tracking: testers record a status for each case in each run, and the system keeps the run history per case.
- Reporting: progress, pass and fail trends, coverage, and defects roll up into dashboards and reports without manual counting.
- Automation and CI results: automated runs upload their results to the same records, so manual and automated coverage show in one place.
Spreadsheet vs test case management system
A spreadsheet or a set of Jira issues works for a few testers on one product. For example, a "Log Out" test case in Jira can carry a custom status field such as "Unexecuted", which a tester updates after the run.
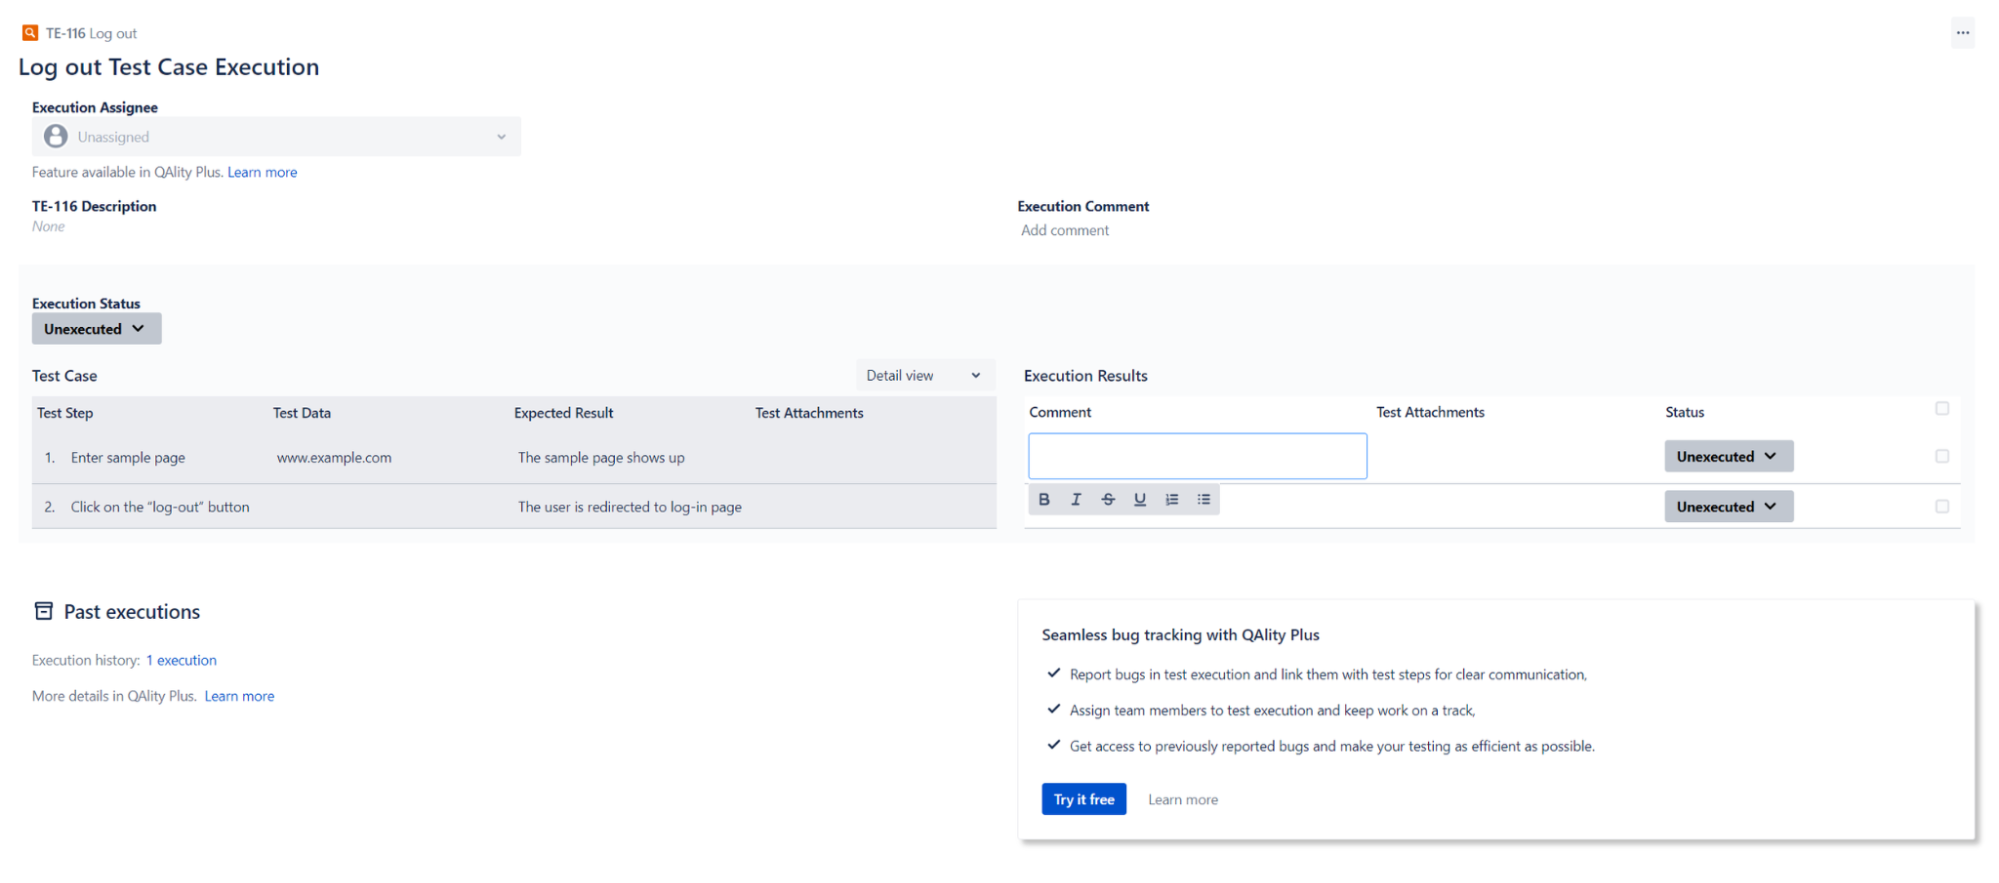
That works at first. As the case count, the team, and the number of releases grow, the manual updates start to cost more than they save.
Need | Spreadsheet | Test case management system |
|---|---|---|
Finding the current case | Copies drift across tabs and files | One repository with version history |
Recording results | Manual edits after each run | Status recorded per run, with history |
Traceability | Hand-maintained columns | Links to requirements and defects |
Automated results | Live in CI logs, rarely reach the sheet | Uploaded from CI to the same records |
Reporting | Rebuilt by hand for each status meeting | Dashboards that update after each run |
Signs it's time to switch:
- Volume and duplicates: the case count makes duplicates hard to spot, and testers rewrite cases that already exist.
- Several testers or locations: more than one person edits the same file, and changes collide.
- Audit or compliance needs: you have to show who changed a case and which version ran.
- Automation: automated results live in CI and rarely reach the sheet, so coverage looks lower than it is.
Before you import, clean up the spreadsheet:
- Give every case a unique ID.
- Agree on one naming convention and rename cases to match.
- Build the folder tree (product area, then feature) before you import.
- Pull repeated steps, such as sign-in, into one shared case.
- Decide the custom fields you need, such as component or risk.
- Delete duplicates and dead cases now, not after the import.
What usually breaks on import: merged cells, all steps in one cell, and free-text statuses such as "ok" or "done?". For the full migration path, see how to move test management out of spreadsheets.
What goes into a managed test case
A managed test case has 2 parts: the content a tester follows, and the management fields that make it findable and traceable. Here is one case from the online store's checkout suite:
Field | Example |
|---|---|
ID and title | CHK-PAY-012: Pay with a saved card |
Preconditions | Signed-in user with a saved Visa card and 1 item in the cart |
Steps | Open the cart, select Checkout, choose the saved card, select Place order |
Test data | Test user checkout-qa-03, test card ending 1111 |
Expected result | Order confirmation page shows an order number, and a confirmation email is sent |
Priority and owner | High; payments QA engineer |
Status and version | Published; version 3 |
Tags | regression, payment, critical |
Linked requirement | User story: pay with a saved card |
Last run | Passed on the latest release candidate |
The first 5 rows are what a tester follows. The management fields are what let you filter, report, and retire cases later. For the writing craft, see how to write test cases. For ready-made formats, use a test case template, and for a large worked set, see these test cases for a login page.
How to manage test cases: the 6-step process
The steps below run in a loop. On an Agile team, most of them happen inside each sprint.
1. Create test cases from requirements
Start from the test plan and the requirements in scope. 4 questions decide which cases you need: what is in scope, where the risk is highest, which cases will be manual and which automated, and who owns each area. Write each case with clear steps, test data, and expected results, and link it to its requirement when you create it, not afterward.
For the online store, 6 of the 40 payment cases come from a new saved-card feature, each linked to the saved-card user story when it was written.
2. Organize them so the right subset is easy to find
Put each case in the right folder, give it an ID that follows the convention, and tag it with its suite and risk. Then group cases into suites, such as smoke and regression, built from existing cases rather than copies. The next section shows a full convention, and our guide to test suites covers suite design.
3. Review before cases go live
A second person reads each new or changed case before it joins a suite: are the steps clear, is the expected result specific, is the requirement linked, and does a similar case already exist? Many teams track this with working statuses such as Draft, In Review, and Published. Our test case review process guide has a checklist.
4. Execute and track status
During test execution, testers record a status for each case in each run. A case typically moves through 5 statuses:
- Untested: the case hasn't run yet in this cycle.
- Blocked: the case can't run because of a dependency, such as an open bug, missing test data, or an environment that is down.
- Failed: the actual result differs from the expected result. Log a defect and link it to the case.
- Passed: the actual result matches the expected result.
- Skipped: the case isn't relevant to this run. Record the reason.
If a case no longer matches the application, mark it for retirement and handle it in step 6 instead of recording a result.
When time is short, run the highest-risk cases first. Our guide to test case prioritization covers the main techniques.
5. Maintain cases as the product changes
Cases go stale when the product changes and the cases don't. Manual testers can adapt steps on the fly, but automated scripts fail until someone updates them, so maintenance cost grows with the size of the automated suite. Strategies that keep it under control:
- Plan for maintenance early: budget time for updates in each sprint, not only before a release.
- Modularize test cases: build shared steps, such as sign-in, once and call them from other cases.
- Choose tools that fit your stack: pick tools that scale with your case count and frameworks.
- Apply coding standards to automated tests: consistent structure makes scripts easier to fix.
- Share knowledge: document conventions and hand over ownership deliberately when people move.
- Audit regularly: review the suite to keep it lean and relevant.
- Train testers to think like users: cases written from the user's view stay valid longer.
A simple hygiene routine for the online store: each sprint, update every case touched by a changed story. Each release, review cases that haven't run in 3 releases, merge duplicates, and separate flaky cases from real failures.
6. Retire what no longer earns its place
Retire cases for removed features, merged duplicates, and cases that can't fail. Archive them, or mark them inactive, rather than deleting them, so their past results stay in the history. A smaller suite that is current gives faster, more trustworthy results than a large one nobody believes.
How to organize test cases
Organization decides whether a tester finds the right case in seconds or writes a duplicate. 4 conventions do most of the work:
- Folders by product area, then feature: for example Checkout, then Payment, then Card.
- IDs that carry the area: for example CHK-PAY-012 for the 12th card payment case, so the ID tells you where a case lives.
- A small, fixed tag set: tags for suite (smoke, regression), risk (critical), and type (api, ui). Agree on the list and don't add tags ad hoc.
- Priority and owner on every case: priority decides run order, and the owner decides who updates it when the feature changes.
Here is the convention applied to the online store's regression suite (illustrative):
Folder | ID prefix | Example tags | Owner |
|---|---|---|---|
Sign-in | SGN | smoke, regression | Accounts QA |
Checkout > Payment | CHK-PAY | regression, payment, critical | Payments QA |
Checkout > Cart | CHK-CRT | regression | Payments QA |
Search | SRC | smoke, regression | Catalog QA |
Custom fields cover anything the conventions don't, such as component, platform, or regulatory scope. Suites are then built from tags or folders, so the smoke suite is every case tagged smoke, not a copy.
Managing manual and automated test cases together
Keep one record per test. The manual case and the automated script that covers it share an ID or a link, so coverage and status aren't split between a spreadsheet and CI logs. Mark the automation status on every case: manual, automated, or to automate.
Results then flow back the same way for both. Testers record manual results in the run, and the CI pipeline uploads JUnit or framework reports to the test case management system after each automated run.
Well-named automated tests document themselves, and some teams use that to skip heavy manual write-ups. You still need one place that shows what is covered, what is manual only, and what hasn't run in months.
Test case management metrics
A few metrics show whether your test cases are healthy, not only whether the build passed:
Metric | What it tells you | Warning sign |
|---|---|---|
Execution progress | Executed cases divided by planned cases in the cycle | Progress stalls with many Blocked cases |
Pass rate trend | Passed cases divided by executed cases, over time | A pass rate stuck at 100% for months can mean cases too weak to fail |
Requirement coverage | Requirements with at least one linked, executed case | Changed requirements with no linked case |
Unlinked cases | Cases with no requirement | A growing share, which usually means duplicates or dead cases |
Never-run cases | Cases not run in the last N releases | Cases that sit unrun for several releases |
Flaky cases | Cases whose result changes without a code change | The same cases failing and passing on reruns |
Case age | Time since a case was last updated | Old cases in areas that changed recently |
For the online store at its last release review (illustrative numbers): 192 of the 200 regression cases link to a requirement, 11 haven't run in 3 releases, 3 are flaky, and 5 are duplicates to merge. The team merges the duplicates, retires 4 of the unrun cases, and moves the flaky ones to a separate review. To share numbers like these, see our guide to the test report.
Common test case management challenges
Challenge | Fix |
|---|---|
Duplicate cases | One naming convention, and search the repository before writing a new case |
Stale cases | A per-sprint update and a per-release review, with owners per folder |
Lost traceability | Link each case to its requirement when you create it |
Manual status updates | Let the tool record results, and upload automated results from CI |
Testers in several locations | Owners per folder and a review step before cases go live |
Outgrowing the spreadsheet | Move to a test case management system once volume, testers, or CI results outpace the file (see Spreadsheet vs test case management system above) |
Best practices for effective test case management
- Write test cases that are concise, clear, and easy to understand, even for someone new to the project.
- Include well-defined preconditions and expected results, so execution is straightforward and repeatable.
- Avoid duplication by reusing shared steps for common actions such as sign-in or navigation.
- Keep test cases up to date by reviewing and refining them as the application changes.
- Tag test cases (for example smoke, regression, critical, performance) to make filtering and reporting easier.
- Link test cases to requirements or user stories to maintain traceability and show coverage. A requirements traceability matrix is the standard document for doing this systematically.
- Archive outdated or deprecated test cases to keep the suite clean and maintainable.
- Define clear ownership, so each test case or test suite has a responsible maintainer.
- Integrate your test management tool with CI/CD pipelines, so automated results land next to manual ones.
- Use dashboards and analytics to find gaps, slow tests, flaky tests, and overall testing trends.
- Version test cases, so the team can see why a case changed and which version ran.
- Use one naming convention across the team, so cases are easy to find and duplicates are easy to spot.
In large projects, add 3 things: an owner per product area, a fixed review cadence, and modular shared steps that many cases call.
What to look for in a test case management tool
When you compare tools, check these criteria against your own team:
- Manual and automated test cases in one repository
- Integration with Jira or your ALM for requirements and defects
- Import of results from your CI/CD pipeline
- Version history and an audit trail per case
- Reports that answer your release questions
- A learning curve your testers accept, and performance as the case count grows
For side-by-side comparisons, see our guides to test case management tools and Jira test management tools.
Test case management in Katalon TestOps
We make Katalon TestOps, so here is how it handles the steps above.
- Repository: test cases reach TestOps through Git sync (GitHub, GitLab, Bitbucket, or Azure Repos), a ZIP upload of a Katalon Studio project, or by being created in the Katalon Cloud repository. Test cases and test suites live in folders you can rename, move, duplicate, and delete.
- Test case detail: each case has a General tab (description, precondition, and steps with Description, Expected Results, and Test Data fields; a step can call another test case), a Linkages tab, and an Executions tab. Details cover status, priority, automation status, assignee, feature areas, test types, tags, and custom fields. Tags sync to linked Katalon Studio projects, and Account Admins can add project-level custom fields.
- Versions: "Save as version" creates a draft minor version and "Save & publish" a published major version. You can compare 2 versions side by side, restore an older one as a new version, and choose which version a manual run uses; the execution records the version that ran. Versions cover manual test case definitions, and metadata changes such as priority don't create a version.
- Review and retirement: the Test Case Activity Analysis report tracks cases by working status (Draft, Ready to review, In Review, and Published), and the status values also include Inactive, which suits retired cases.
- Traceability: the Linkages tab shows a visual map of the requirements and defects linked from Jira or Azure DevOps, plus related test cases and the cases a test calls or is called by.
- Import and export: CSV import maps fields automatically, shows a preview, and can include requirement linkages (about 500 cases per file is recommended). A one-time import from Azure DevOps is also available. You can export selected cases or folders to Word or CSV.
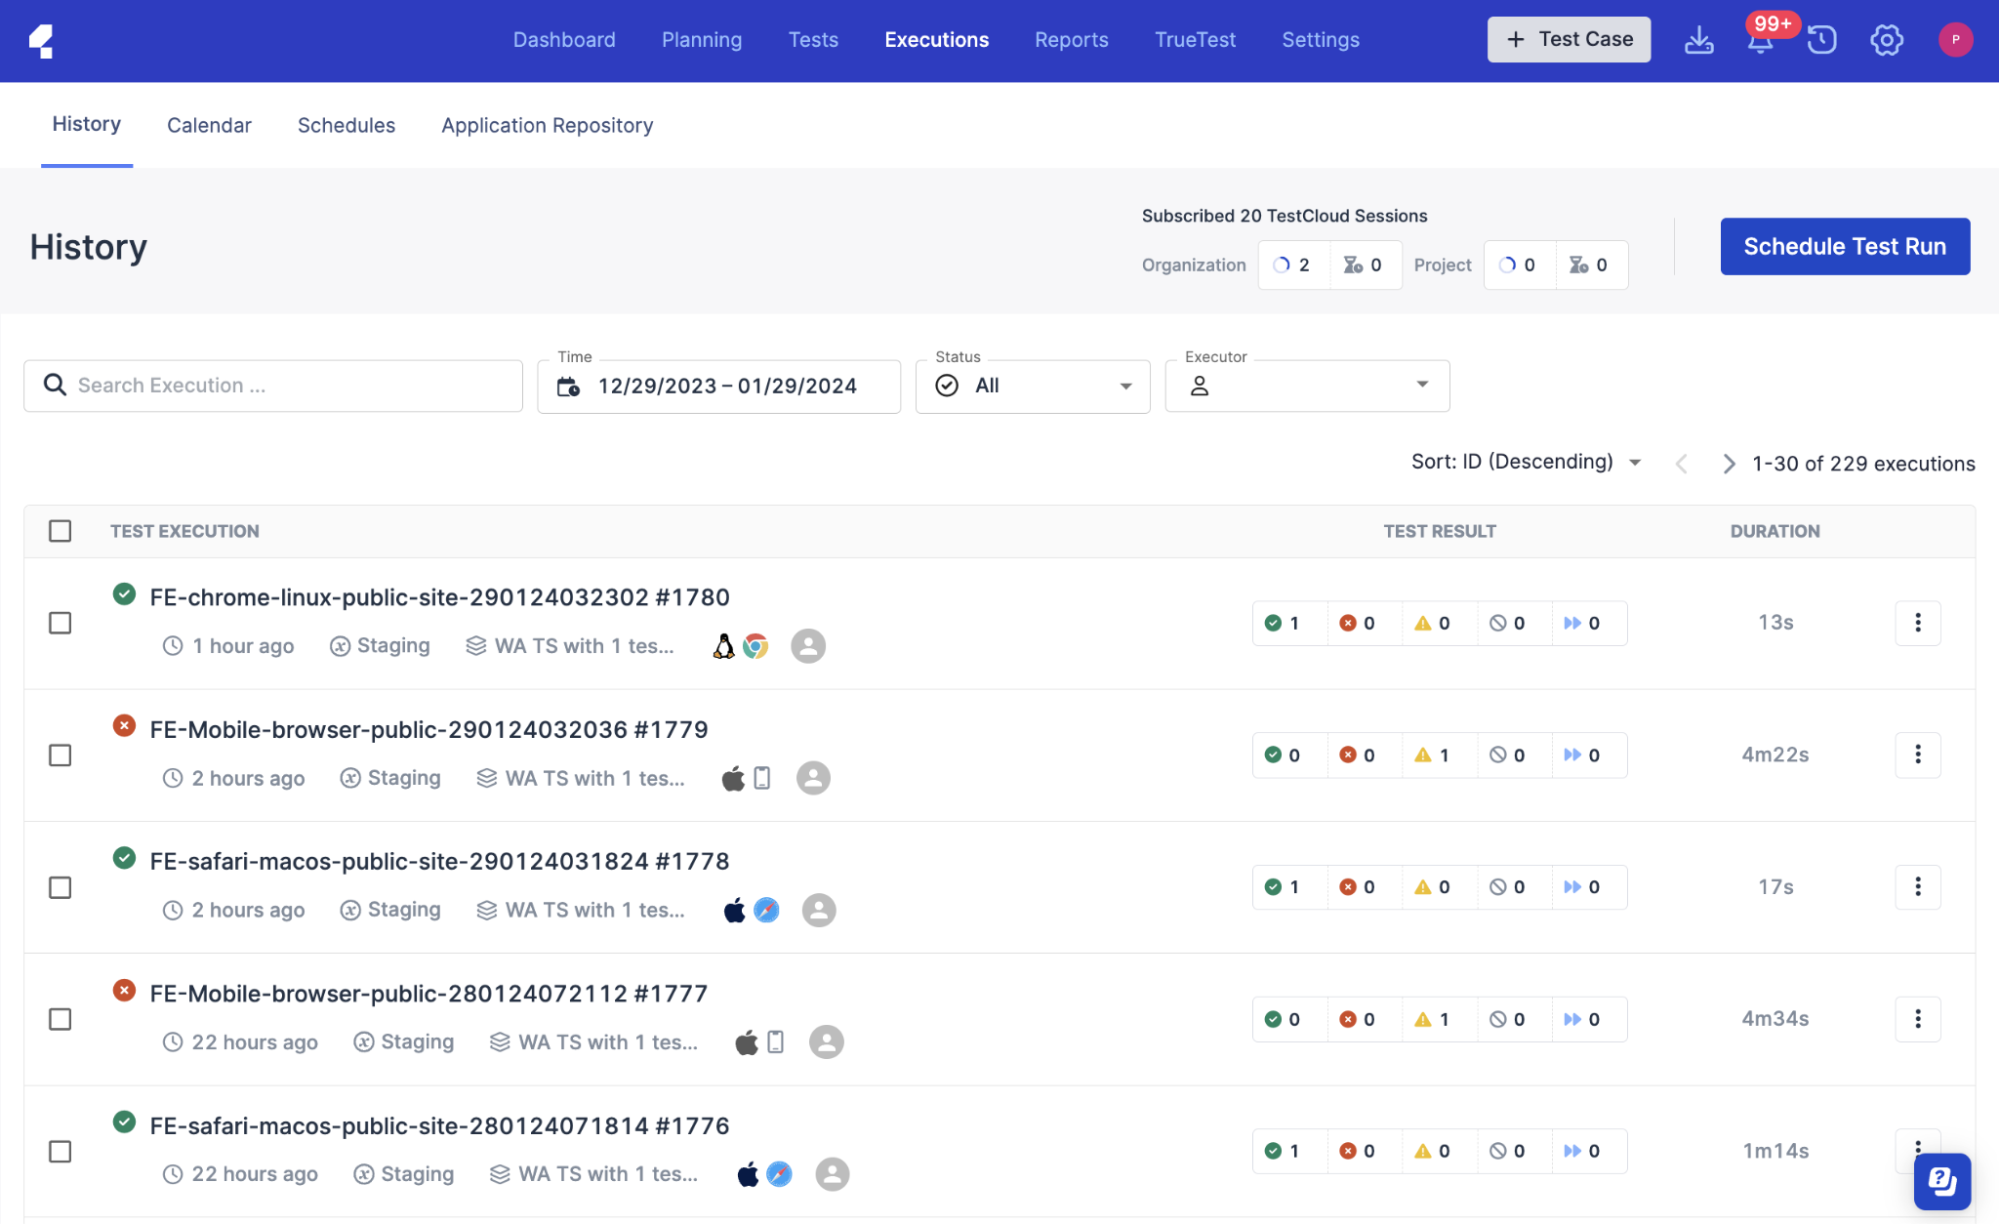
- Manual and automated runs: a test suite is Manual or Automated, not a mix. Manual runs take an executor, an optional release or sprint, and a target configuration, and can start now or be scheduled, and testers can execute them themselves or with Run with AI. CI pipelines upload Katalon, JUnit, or Katalon Recorder reports with the Report Uploader, and the results appear in TestOps reports alongside your manual runs.
Katalon AI Assistant can also refine a requirement and generate linked test cases for review. For setup details, see the docs on managing test cases and test case versions.
Putting it together
For the online store, test case management means the 200 regression cases live in one repository, organized by area and risk, linked to their user stories, with manual and CI results on the same records and a review every release. That keeps the suite small enough to trust and current enough to run.
To go further, the test management guide covers planning and sign-off, and a test case template gives you ready-made formats.
Frequently asked questions
Test management covers the whole testing effort for a release: planning, people, environments, execution, defects, monitoring, and the go or no-go decision. Test case management is one part of it: keeping the test cases, their versions, and their results complete and current. Our test management guide covers the wider discipline.
Test execution is running the tests and recording the result of each run. Test case management is the ongoing work around the cases themselves: creating, organizing, linking, versioning, and retiring them, including the history of every execution. See our test execution guide.
Partly. Jira can hold a test case as an issue with a custom status, which works for a few dozen cases. On its own it has no test run, step result, or coverage model, so teams add a Jira-native test management app or connect a standalone tool that links cases to Jira stories and bugs. See our list of Jira test management tools.
Update cases touched by changed stories every sprint, and run a wider review each release: retire cases for removed features, merge duplicates, and check cases that haven't run in several releases. Cases that fail without a code change go to a flaky-test review, not a bug report.
Write them as soon as a requirement or user story is agreed, before or alongside development, so they can be reviewed with the story and linked from the start. Automated scripts usually follow once the feature is stable enough to test.
There's no right number. Keep each case that checks a current requirement or a known risk and that would fail if the feature broke. Retire duplicates, cases for removed features, and cases that can't fail.
A test case repository is the central store where a team keeps its test cases, organized in folders and suites with fields such as priority, owner, tags, and linked requirements, plus version and execution history. It's the core of a test case management system.
TCM means test case management, the upkeep of a team's test cases and their results. TCMS (test case management system) is the tool that holds them, sometimes also called a test management tool.
Test everything. Ship with confidence.
From generating test cases to spotting failures, Katalon's AI works across your entire pipeline, automatically.
