


In modern software development, "moving fast" is the goal, but "breaking things" is a luxury few teams can afford. Every time a developer pushes a bug fix, an optimization, or a shiny new feature, they risk inadvertently breaking a feature that was working perfectly five minutes ago.
Regression testing is the practice of re-running existing test cases after a code change to confirm that established functionality still works. Teams run it after bug fixes, new features, configuration changes, and integrations. Because it is repetitive by nature, regression testing is a strong candidate for automation, often running in CI/CD pipelines as a safety gate before production.
In modern software development, "moving fast" is the goal, but "breaking things" is a luxury few teams can afford. Every time a developer pushes a bug fix, an optimization, or a shiny new feature, they risk inadvertently breaking a feature that was working perfectly five minutes ago.
This is where Regression Testing becomes your safety net. In this guide, we’ll explore how to build a regression strategy that doesn't just catch bugs but actually accelerates your release cycle.
What is regression testing?
Regression testing is the practice of re-running existing test cases to ensure that recent code changes haven't negatively impacted established functionality. It answers one question: did this change break anything that already worked?
What counts as a regression?
A regression is any defect where a feature that used to work stops working after a change. The name comes from the idea that the software has "regressed" to a worse state. When a change in the "Discount" module accidentally breaks the "Payment" gateway, you've hit a regression.
A regression suite usually covers:
- Core user flows that would stop a user's journey if they broke, such as login, search, and checkout.
- Code and data shared with the change, such as modules that call the same service or read the same tables.
- Integrations, such as third-party systems and API contracts that downstream services depend on.
The Comparison Guide: Understanding Where Regression Fits
To master regression testing, you must understand where it sits in the broader QA landscape. It is often confused with other testing types, but its intent is unique.
1. Retesting vs. Regression Testing
While both involve running tests again, they answer two different questions:
- Retesting (Verification): "We found a bug. Did the developer actually fix it?" (Focuses on the specific failure).
- Regression (Side Effects): "The bug is fixed, but did that fix break anything else in the system?" (Focuses on the broader stability).
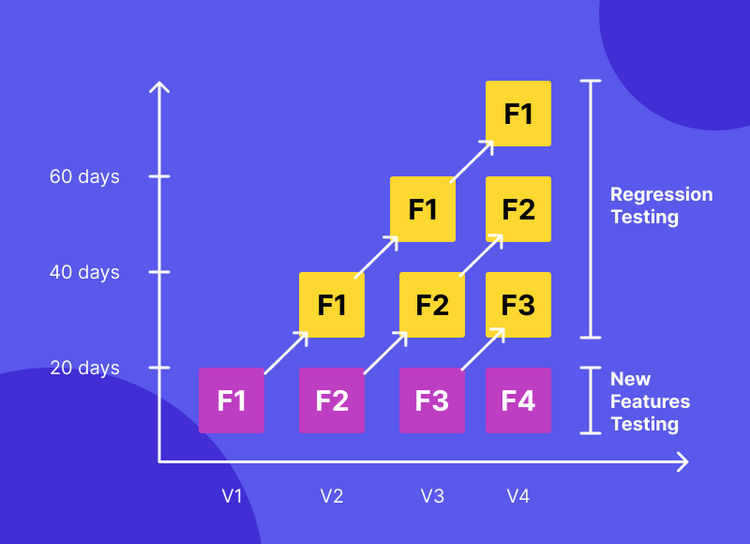
2. New Feature Testing vs. Regression Testing
Think of these as the two pillars of any release. One looks forward, the other looks backward.
Aspect | New Feature Testing | Regression Testing |
|---|---|---|
Primary Goal | Validate that new code meets requirements. | Validate that existing code still works. |
Scope | Narrow and deep (specific to the change). | Broad (covering core stable features). |
Timing | Performed during initial development. | Performed after integration or bug fixes. |
Automation | Often manual (code is still shifting). | Highly recommended (code is stable). |
Smoke, Sanity, and Regression: The Testing Hierarchy
To build an efficient pipeline, you shouldn’t run your entire regression suite every time a developer saves a file. Instead, QA teams use a tiered approach to save time and resources.
1. Smoke Testing (The Gatekeeper)
Smoke testing is the preliminary check. Its goal is to verify that the most critical functions of the application work (e.g., Can the app even launch? Can a user log in?).
- Relationship to Regression: If the "smoke" tests fail, the build is rejected immediately. You don't waste time running a full regression suite on a broken build.
2. Sanity Testing (The Targeted Check)
Sanity testing is a narrow, deep dive into a specific component after a bug fix or code change. It is essentially a "subset" of regression testing.
- Relationship to Regression: While regression testing checks the entire system, sanity testing only checks the specific area that was changed to ensure the logic is sound before proceeding to broader testing.
3. Regression Testing (The Safety Net)
This is the final stage. Once the smoke is cleared and the specific fix is deemed "sane," you run your Regression Suite to ensure that these new changes haven't caused a "ripple effect" and broken unrelated parts of the software.
Should Regression Testing Be Automated?
The short answer is yes. While manual testing is essential for exploring new features or checking UX "feel," regression testing is repetitive by nature. This makes it the perfect candidate for automation.
The Banking Example: The Cost of Manual Slowness
Consider a banking app that updates its "Currency Exchange" rates. To release this small update, a manual tester might spend 4 hours checking login security, account balance displays, and money transfer functionality just to be safe. If you update the app twice a week, that’s 8 hours of human labor spent just "checking old stuff."
Automation with something like TrueTest turns those 4 hours into 5 minutes of background processing. This allows your team to focus on finding complex bugs in the new currency feature rather than clicking the "Login" button for the thousandth time.
Looking beyond traditional automation, agentic QA takes this further. Instead of humans maintaining and updating regression scripts when the application changes, AI agents can self-heal broken tests, generate new regression cases from requirements, and triage failures automatically, making regression testing one of the strongest use cases for agentic adoption.
📝 Read More: Complete Guide to Automated Regression Testing
Why Bother? Benefits and Hard Truths
The Benefits
- Prevents Cascading Failures: Catches the "ripple effect" where a small UI tweak breaks a backend database call.
- Enables Agile Velocity: Gives developers the confidence to refactor code without fear of a total system collapse.
- Supports CI/CD Pipelines: Automated regression tests act as safety gates, ensuring each integration is stable before it reaches production.
The Challenges
- Maintenance Heavy: As your app evolves, so does your suite. Keeping scripts updated with UI changes is a constant task.
- The Time Sink: Without automation, regression becomes a major QA bottleneck as the project grows.
- Risk of Overlooking Bugs: Under tight timelines, it’s easy to miss small regressions in complex systems.
When Is Regression Testing Done?
Regression testing is typically triggered by:
- New feature introductions or requirement updates.
- Bug fixes and code optimizations.
- Third-party system integrations or configuration changes - especially API contract changes that downstream services depend on.
- UI/UX updates or patch releases - where visual regression testing catches unintended layout shifts or styling bugs.
Types of regression testing
Not every change needs the same depth of regression. The common types differ in how much of the suite they run:
Type | What it runs | When to use it |
|---|---|---|
Retest-all | The entire regression suite | Major releases, large refactors, or platform upgrades |
Selective | Only tests linked to the changed code or modules | Routine fixes and small features |
Progressive | Existing tests plus new cases for changed requirements | When the spec itself changes |
Corrective | Existing tests, unchanged | Code changes with no change to requirements |
Partial | The changed module and the modules that interact with it | Localized changes with known dependencies |
Unit regression | Unit tests for the changed code in isolation | Every commit, as the fastest feedback loop |
Most teams mix these. For example, they might run unit and selective regression on every pull request and save retest-all for release candidates.
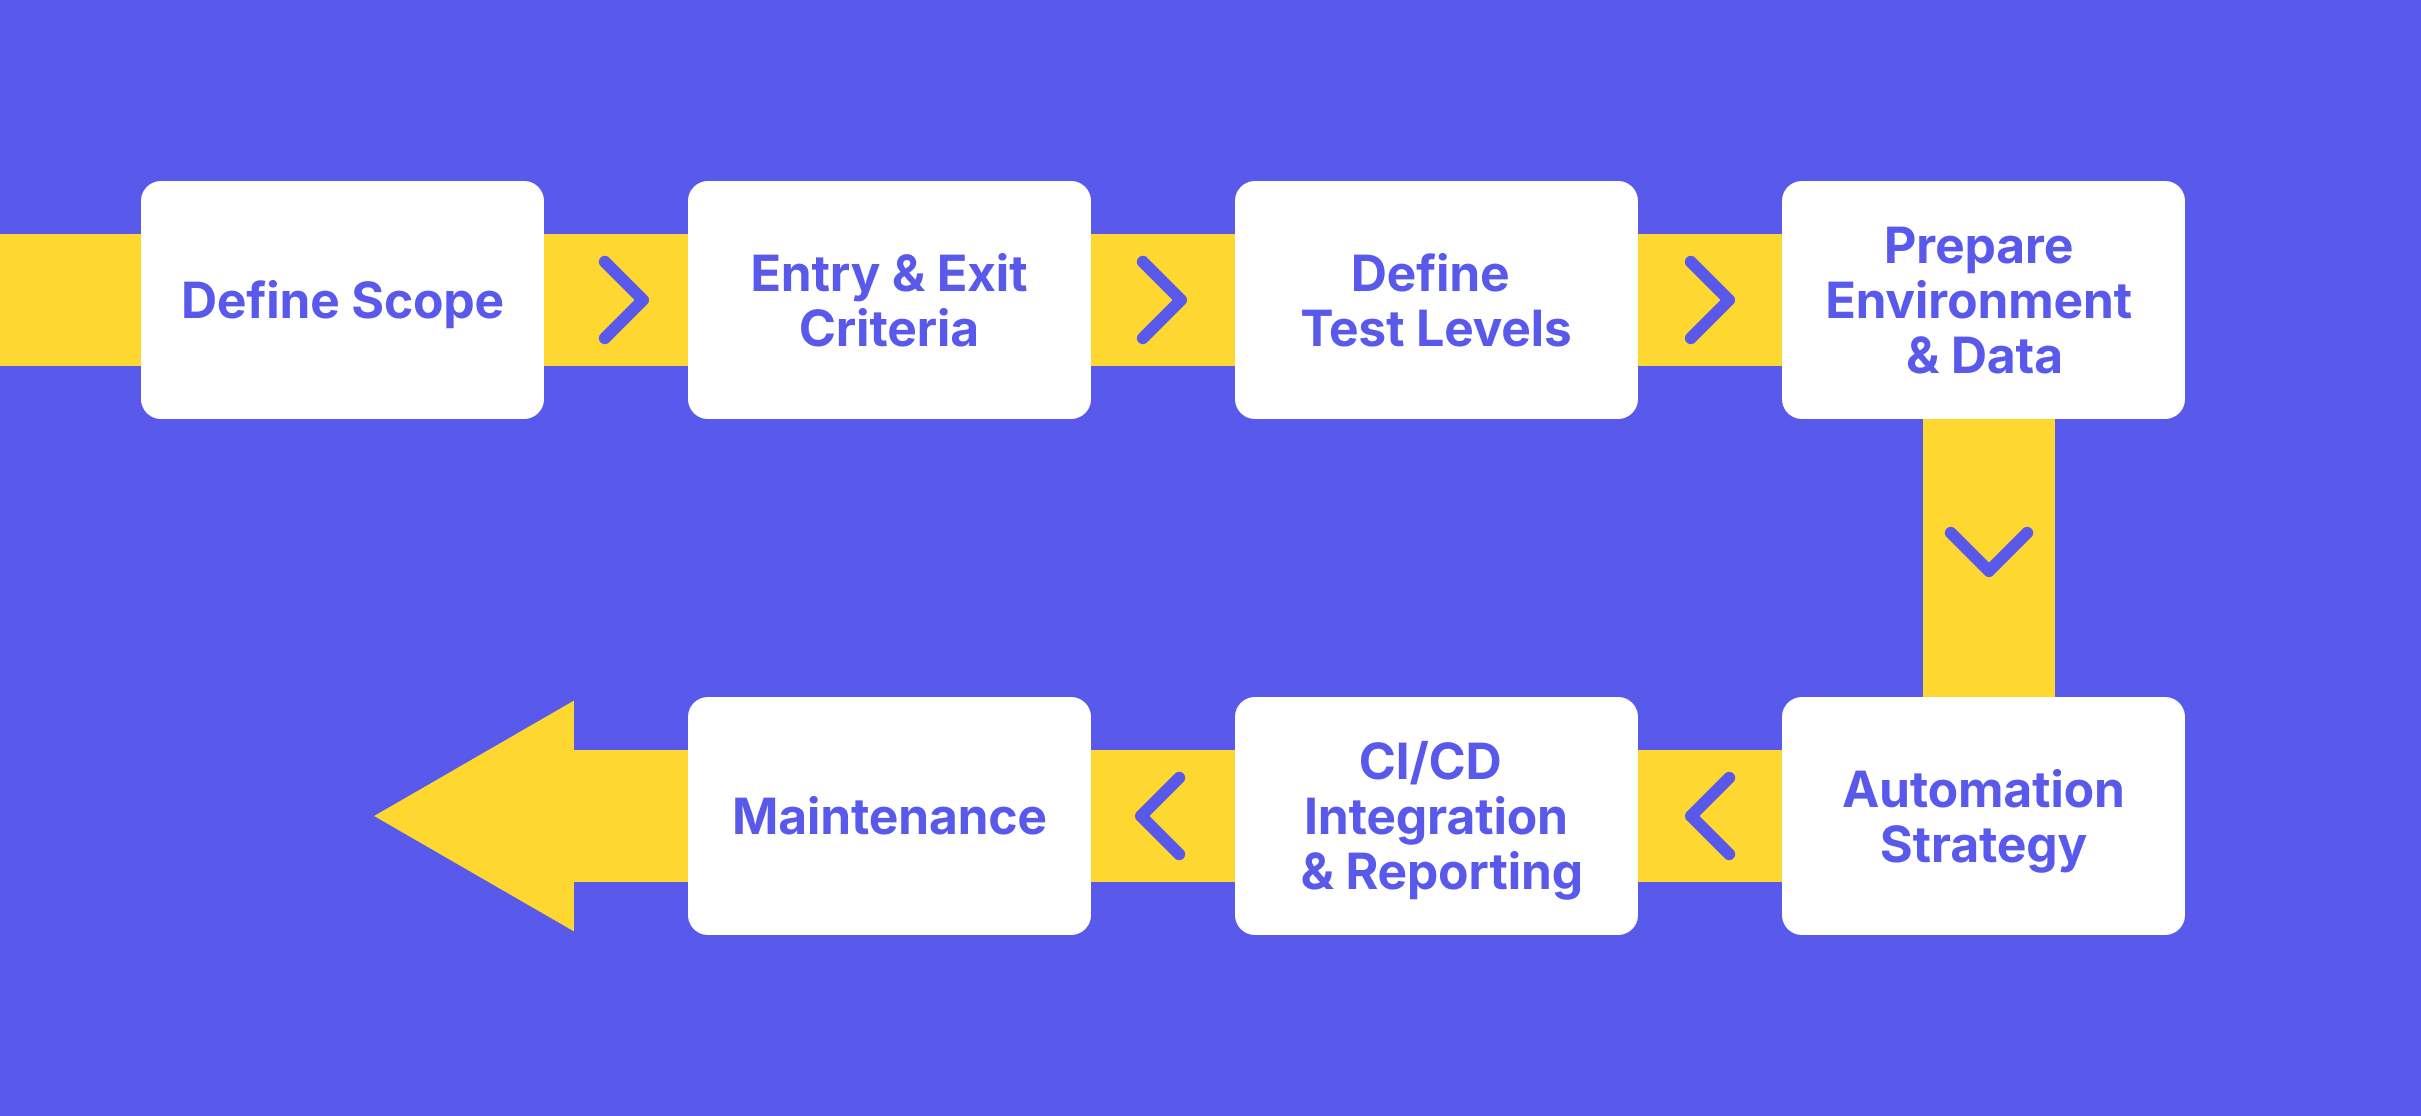
How to do regression testing: a 7-step framework
- Detect changes and define scope. Identify what changed (fix, feature, or config) and prioritize testing by risk tier. Focus on high-risk core flows first.
- Set entry and exit criteria. Define clear start conditions (stable build, smoke tests passed) and stop conditions (95% pass rate, zero critical bugs) so runs stay efficient.
- Define test levels. Use the test pyramid to balance speed with coverage: 70-80% unit, 15-20% integration, and 5-10% E2E.
- Plan environments and data. Isolate test environments using Docker or mocks, and use modular test data to prevent flakiness and false failures.
- Set an automation strategy. Aim for 70-90% automation on critical paths, and save complex or visual scenarios for manual exploratory testing.
- Integrate with CI/CD and report. Run tests automatically at the pull request stage with gatekeeping policies. Use dashboards to track pass rates, execution times, and defect trends. For example, in Katalon TestOps, teams can access dashboards that highlight testing efficiency and defect density after every run.
- Maintain the suite. Practice "sprint pruning": retire obsolete tests and refactor flaky ones each sprint to keep the suite lean and sustainable.
📝 Read more: Regression Test Strategy: A 2026 Guide to Planning & Best Practices
How to choose which regression tests to run
Running the full suite on every change slows feedback. Most teams combine these selection methods:
Method | How it works | Best for |
|---|---|---|
Risk-based | Rank tests by business impact and likelihood of failure, then run the "crown jewels" first | Release gates under time pressure |
Change-based | Map tests to code and run the ones that touch changed files or modules (change impact analysis) | Pull request checks |
Tag-based | Label tests (for example, smoke, payments, api, or critical) and run suites by tag | Pipelines with different stages |
Failure history | Prioritize tests that failed recently or often in the changed area | Historically unstable modules |
A practical pattern is to run a change-based and tag-based subset on every pull request, then run the full suite nightly or before release.
Write these selection rules into your test plan so everyone knows which tests run at each stage and why.
Balancing New Features with Regression
The biggest struggle for QA leads is deciding where to spend limited resources. Alex Martins, a veteran with 20+ years in software quality, shares how to maintain this balance when the dev team is moving at full speed:
Regression Testing Best Practices
- Prioritize High-Risk Areas: Focus on the "crown jewels" of your app - features that would stop a user's journey if they broke.
- Automate Wisely: Manual regression is slow and error-prone. Use tools to automate repetitive high-impact tests.
- Maintain Your Suite: Regularly prune outdated tests and update scripts to stay relevant with the UI.
- Shift Left: Integrate regression into your CI/CD pipeline to catch bugs the moment code is integrated.
- Parallel Testing: Run tests across multiple browsers and OSes simultaneously to reduce execution time.
📝 Read more: Automated Regression Testing: Strategy, Tools & Best Practices
Top Regression Testing Tools for 2026
1. Katalon
Katalon helps teams automate regression for web, API, and mobile apps without starting from scratch. It bridges the gap between manual and automated testing with its Keyword Library and low-code capabilities.
2. Selenium
The open-source standard for web testing. It is incredibly powerful but requires significant coding expertise to maintain. Ideal for teams with dedicated SDETs.
3. Playwright
A modern framework known for its speed and "auto-waiting" features, making it a favorite for testing modern web applications built on React or Vue.
for more of a deep-dive into our guide on the best regression tools for 2026.
Conclusion
Regression testing is more than just a safety check; it’s the foundation of user trust. By balancing the excitement of new features with the stability of a robust regression suite, you ensure your product remains solid as it scales.
Frequently asked questions
Regression testing is the process of re-running existing tests after code changes to ensure that new updates, bug fixes, or enhancements do not break existing functionality. It verifies system stability and consistency after modifications in the software.
Regression testing is essential because even small code changes can cause unexpected issues elsewhere in the application. It ensures software reliability, supports Agile and CI/CD workflows, and helps catch regressions early before release, preventing costly production bugs.
Regression testing should be done whenever the codebase changes — such as after bug fixes, new features, UI updates, configuration changes, patch releases, or third-party integrations. It confirms that the existing features still behave as expected after updates.
Yes. Regression testing is highly repetitive, predictable, and ideal for automation. Automated regression tests speed up execution, improve accuracy, and integrate seamlessly into CI/CD pipelines. However, manual regression testing is still valuable for exploratory or visual validation.
Top tools include Katalon Studio, Selenium, and Watir, each supporting automated regression test suites across web, API, and mobile apps.Best practices include: Prioritizing critical test cases Automating repetitive tests Maintaining and updating the test suite regularly Running regression tests continuously in CI/CD pipelines Using parallel testing to save time
Test everything. Ship with confidence.
From generating test cases to spotting failures, Katalon's AI works across your entire pipeline, automatically.
