


Katalon AI Test Runner runs your existing manual test cases as-is in Katalon TestOps, verifies every step with a separate AI, and keeps evidence for each verdict.
Manual test cases hold a lot of what your team knows about the product: the flows that matter, the data that breaks things, the checks that catch regressions. Running them by hand every release is where the hours go, and it is the work that gets squeezed first when a release date moves.
Katalon AI Test Runner is now available in Katalon TestOps as Run with AI, bringing agentic test execution to your manual test library. It reads your natural-language manual test cases, runs them against your application, checks each step, and records results and supporting evidence. Your testers keep the work that requires experience, judgment and subject-matter expertise.
What Katalon AI Test Runner Does
Katalon AI Test Runner is an agent that executes natural-language test cases against your application. It follows each step in a cloud browser on Katalon TestCloud, compares what happens with the expected result, and records the outcome. It is literally running your existing manual test cases, in natural language, with no script to write and no framework to build first.
That is a different job from most AI for manual testing. Many AI tools for manual testing suggest scenarios or help draft test cases. Katalon AI Test Runner takes the test cases your team already wrote and runs them. For how agents fit into a QA team more broadly, see What Is Agentic QA?
What does not change is who owns the judgment. Deciding what to test, how serious a failure is, and whether a build is ready all stay with your testers. The runner takes over the repetitive part: following the same steps, release after release.
How a Run Works
Every run follows the same five steps.
- Choose the tests. Start Run with AI from a test case, a test suite or a manual test run. You can also schedule a run, or start one from Katalon AI Assistant or from an AI assistant connected through the Katalon MCP server.
- Check readiness. Before the run, the AI reviews each test case for clarity and completeness and flags gaps. A tester provides clarifications to close any gaps once, instead of working around them every cycle.
- Run at scale. Independent test cases run in parallel in the cloud, and a data-driven test case runs one session per dataset row. Repeat runs do not use AI; they are fully deterministic. If a step fails because a screen changed, the runner hands that step to the AI, which adapts the execution at runtime and updates the test case accordingly.
- Verify every step. A separate, read-only AI judges each step from screenshots and actions, and fixed rules decide the verdict. If a step is unclear, the runner retries it and then hands it to a person instead of passing it. The AI doing the work never approves its own result, which is the argument in The Agent Passed Its Own Test. That's the Problem.
- Review the results with proof. Every step leaves a verdict and evidence, so a reviewer can open the proof instead of trusting a status.
Pass or Fail, With Evidence for Every Step
Before it reports a pass or fail, the AI checks the evidence for each step. Each step is marked passed or failed. Failed steps carry an AI verdict: the AI’s assessment of what went wrong, the expected result next to the actual result, and a suggested next action. When the cause is a real product bug, the AI verdict says so, instead of leaving you to work out whether the test data, the environment or the application caused the failure.
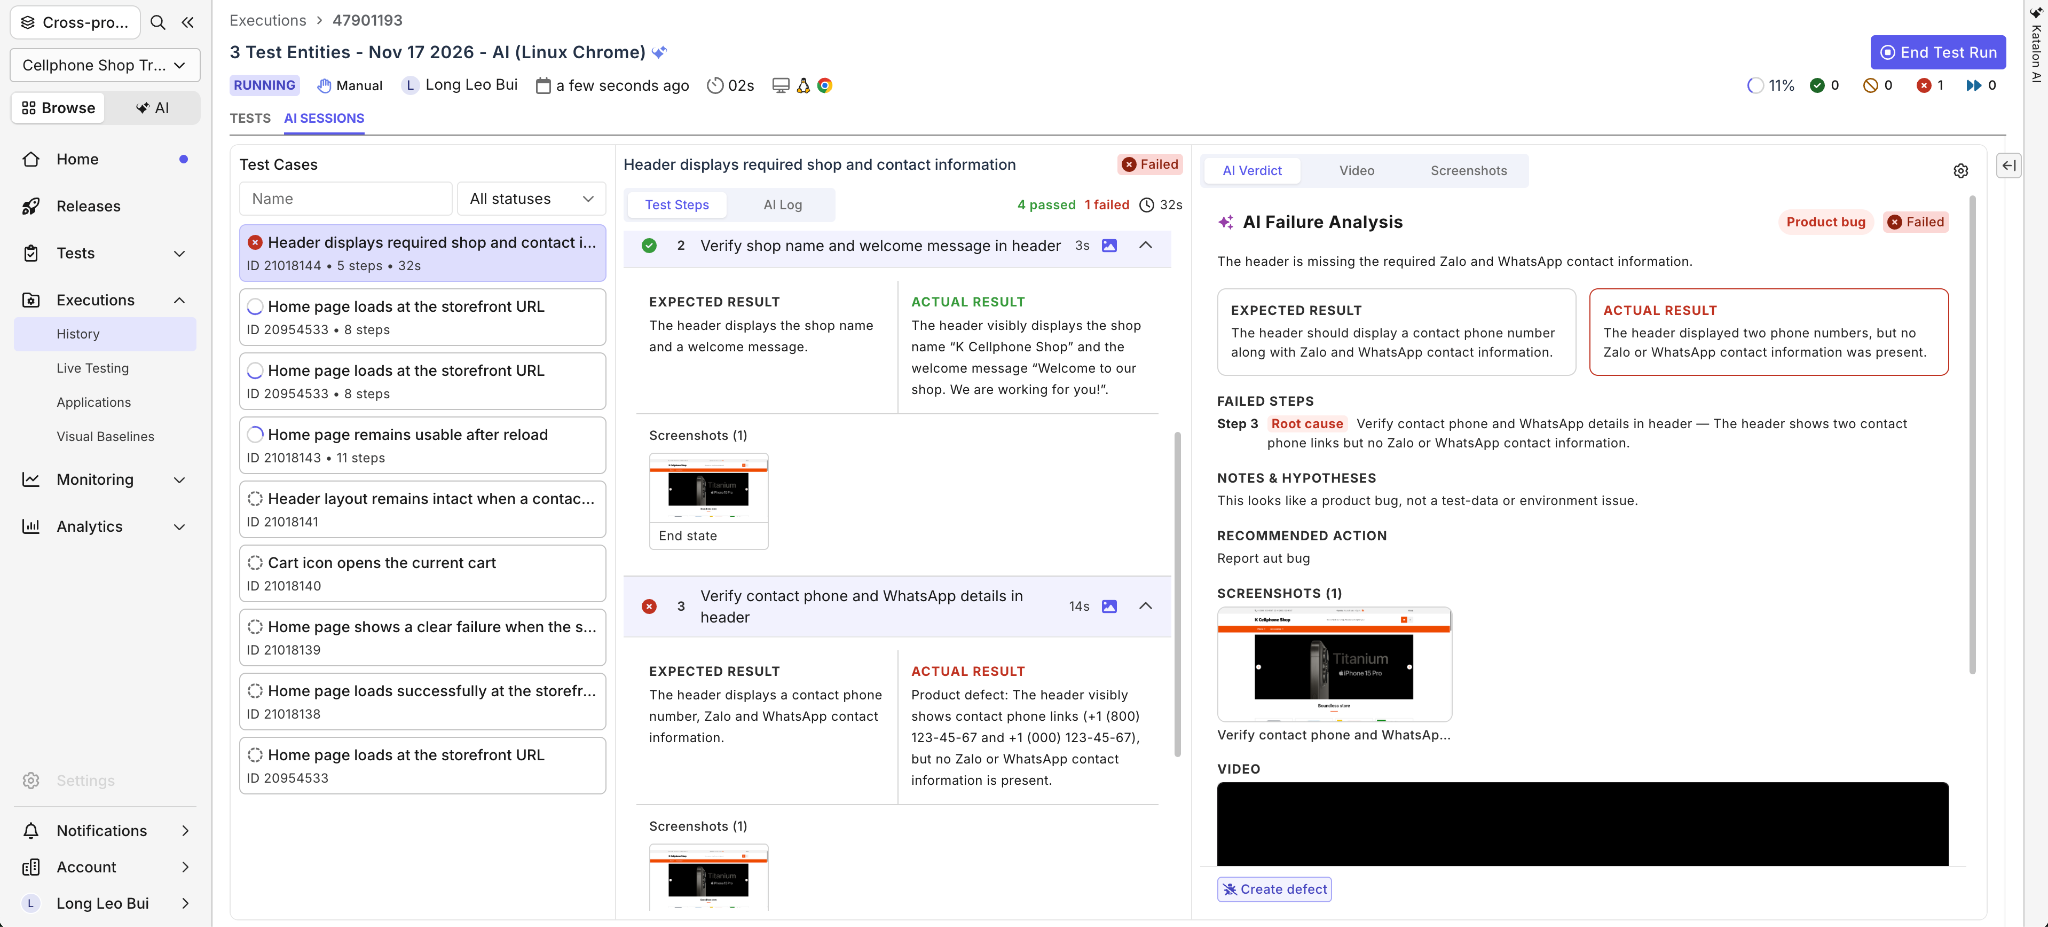
A failed step in an AI Session. The AI Verdict panel shows the expected and actual result, a Product bug label, the root cause, a recommended action and a Create defect button.
Every result comes with evidence that testers, leaders and auditors can review: video, screenshots and the AI log for each step, kept as a recorded execution history. From a failed result you can create a defect in Jira or Azure DevOps with the steps to reproduce and a link back to the result.
For anything that matters to a release, review the evidence before you trust the result. A green status is a claim, and the evidence is the proof, which is the point of Katalon AI Test Execution and False Passes.
Where It Runs and What It Connects To
Runs execute on Katalon TestCloud, against web applications in Chrome or Edge on Linux, Windows or macOS, and against mobile applications. For an application on a private network, such as a staging environment behind a firewall, choose Katalon Tunnel or IP allowlisting when you start the run.
Credentials belong in Secrets & Variables in Katalon TestOps. Logins that use one-time passcodes work when the code is sent by email to a configured test inbox, and the codes are hidden from results and logs.
Results land in Katalon TestOps test runs and reports. From there you can push results to Azure DevOps Test Plans or Xray, and create defects in Jira or Azure DevOps with the evidence attached.
Who Katalon AI Test Runner Is For
Katalon AI Test Runner is built for teams that run regression by hand every release and have a manual QA team with deep business and application knowledge. It gives those teams the ability to run their existing manual tests in a fully automated fashion, without hiring automation engineers and without asking testers to learn a new framework or scripting language. It is manual testing automation that keeps the test cases where they are, as your team already wrote them.
Running the steps stops being the job, and reviewing the results the AI flagged becomes the job. Testers read the flagged results, investigate failures, and spend the freed time on exploratory testing, risk analysis and change impact analysis. For that shift, read Manual Testers Are Getting Promoted. For those who are tired of trying to automate tests and never reaching the test automation coverage they wanted, read Your Manual Tests Are Already Automation.
How to Get Started
You need three things: Katalon TestOps, manual test cases written as steps with expected results, and an application that Katalon TestCloud can reach. Start with one test case that a new teammate could follow without asking questions. Put the application URL in the steps, keep logins in Secrets & Variables, and start the run from the test case, a test suite or a manual test run.
Watch the first run. The moments when the runner pauses to ask for input are the most useful part, because each question points to something the test case does not say. Add the answer to the step, and the readiness check will have less to flag next time.
For a step-by-step walkthrough, watch the Katalon AI Test Runner how-to series on YouTube: creating test cases from requirements, running them with AI in parallel, and reading the results, reports and analytics.
Frequently asked questions
Katalon AI Test Runner is an agent in Katalon TestOps that executes natural-language test cases against your application. It checks every step with a separate AI and leaves a verdict and evidence for each one.
Most AI tools for manual testing help write or suggest test cases. Katalon AI Test Runner runs the manual test cases you already have, verifies each step with a separate AI, and keeps the evidence. Your testers still decide what to test and whether a release is ready.
No. It takes over repetitive execution, and testers review failed results and any step the AI could not confirm. The judgment work stays with people: what to test, how serious a failure is, and whether a release is ready. For the longer answer, read Is Manual Testing Dead?
No. The runner executes your test cases in natural language, as written. You do not convert them into scripts first, and no framework has to be built.
Repeat runs follow the recorded path, without AI, until a step no longer matches. The AI then finds the new way, an independent AI checks it, and the test case is updated. A real bug is still reported as a failure and is not healed away.
Yes. Choose Katalon Tunnel or IP allowlisting when you start the run, so the cloud browser can reach your private environment.
Katalon does not offer Katalon AI Test Runner as a way to cut headcount. It takes repetitive execution off your testers, so the team you already have can run more tests and spend valuable time on exploratory testing, risk analysis, change impact analysis and failure investigation.
Test everything. Ship with confidence.
From generating test cases to spotting failures, Katalon's AI works across your entire pipeline, automatically.
